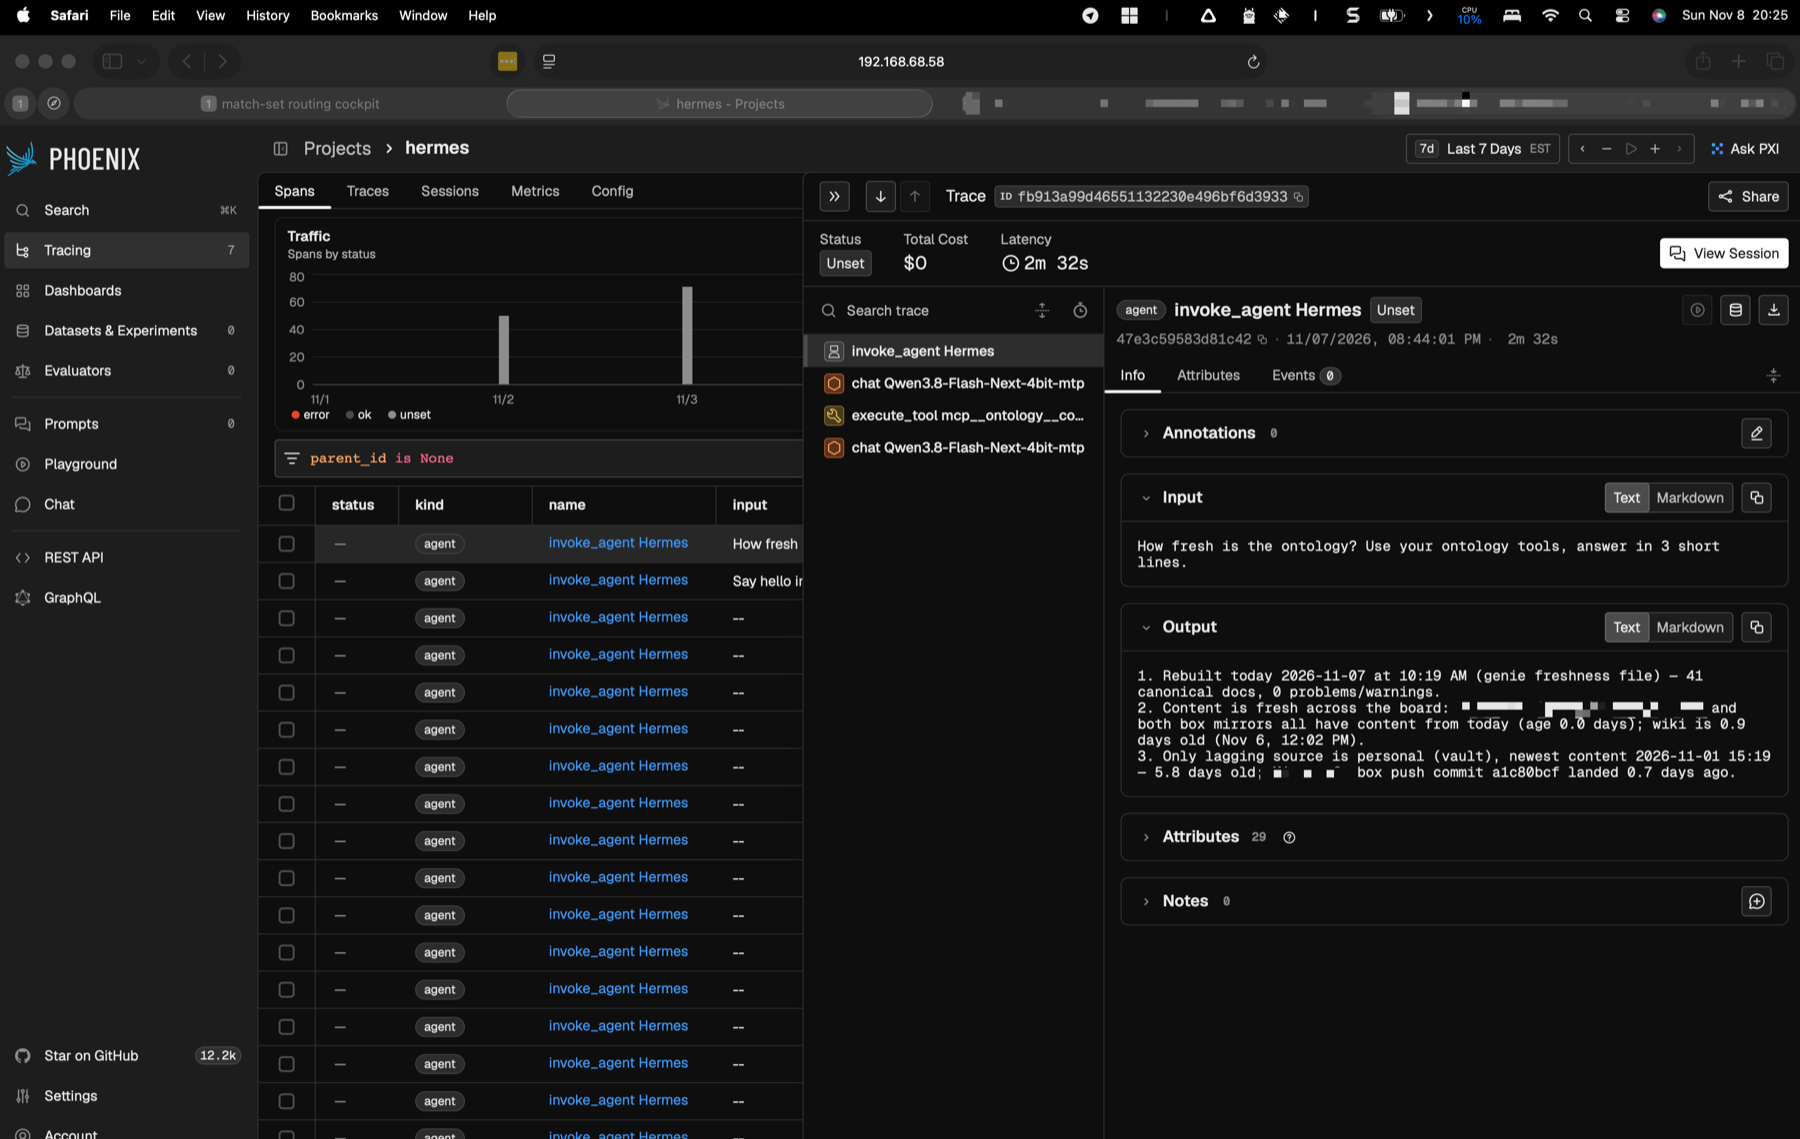
Arize Phoenix showing 1 Hermes trace: the agent span, 2 model calls on Qwen3.8 Flash Next, and 1 tool call, with my question as the input and the answer as the output.

Weekday Judge, Weekend Judge, and Now a Microscope

BLUF (bottom line up front): For a few weekends now I’ve been grading my own AI. A local model judges it every night of the week, and I judge it by hand every weekend. This weekend 2 talks from the AI Engineer conference said out loud what my grading had already been telling me, and I turned what they said into code the same day, not the same month. I also opened up my traces, so now I can follow every question from the words I typed to the answer the model gave, step by step, tool by tool. Weekday judge, weekend judge, and now a microscope :-) ...
November 8, 2026 · 9 min · Fabian Williams
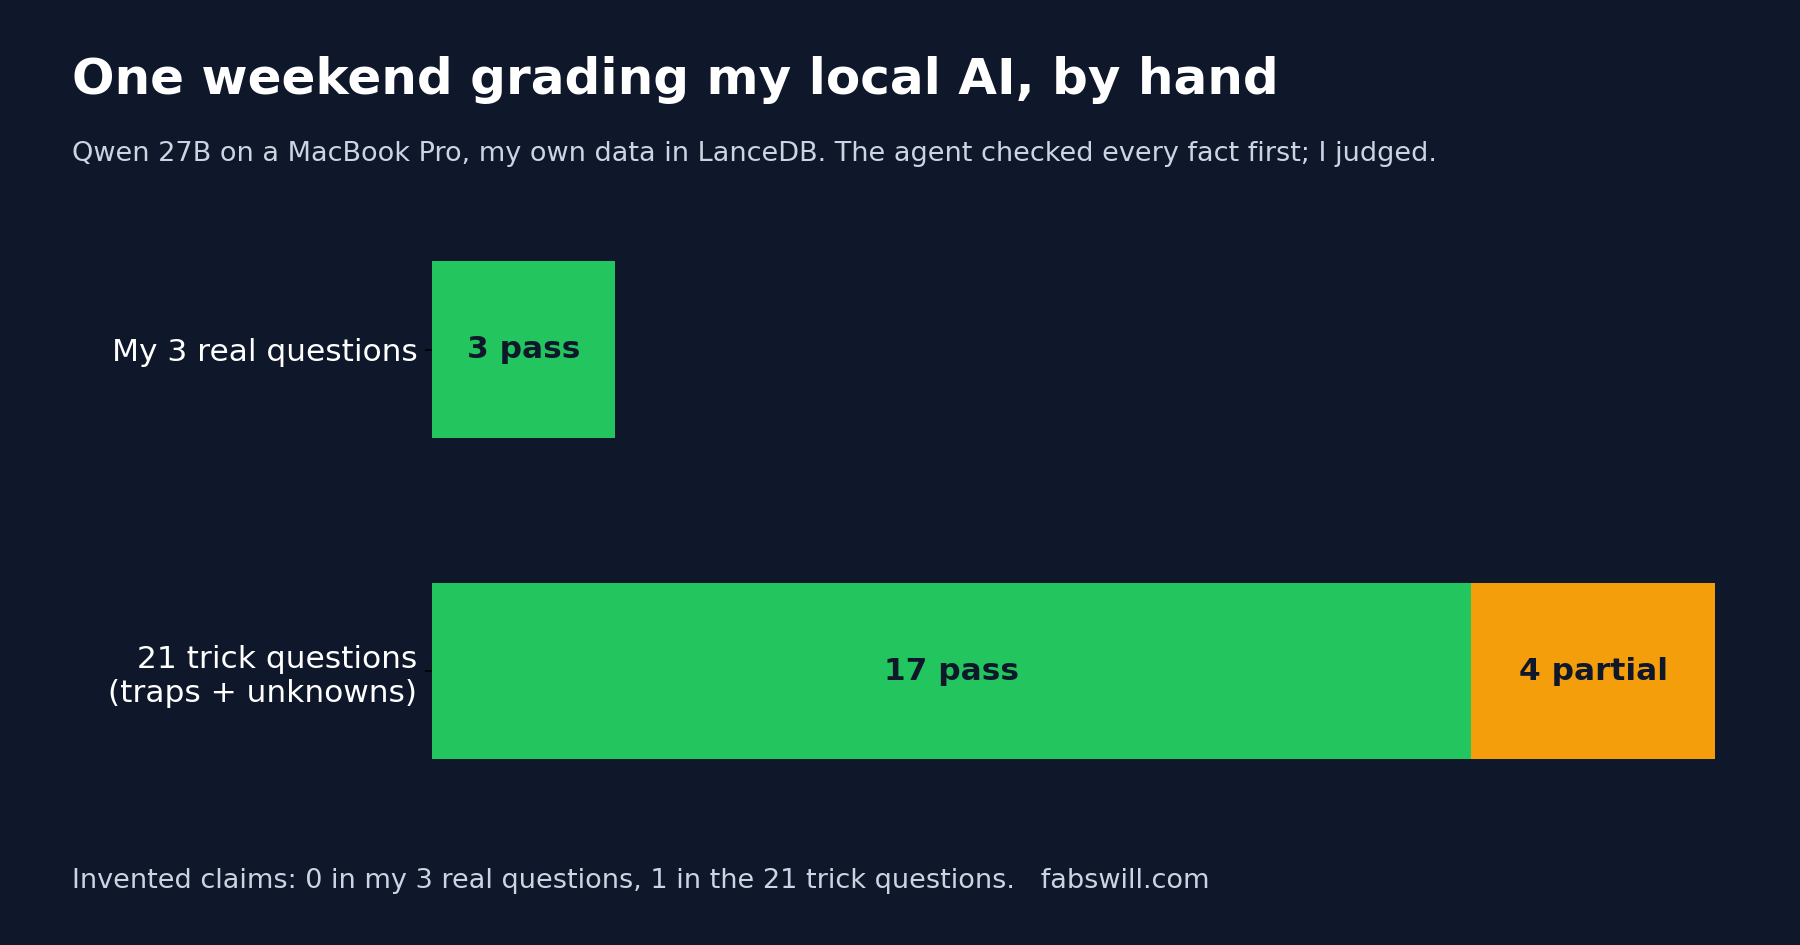
A bar chart titled One weekend grading my local AI, by hand. My 3 real questions: 3 pass. 21 trick questions, traps and unknowns: 17 pass, 4 partial, 0 fail. Invented claims: 0 in the 3 real questions, 1 in the 21 trick questions.

Don't Worry About the Terminator. Worry About David.

BLUF (bottom line up front): I’m just starting too. My data has lived in my Obsidian vault, my 2nd brain, for a while, but the practices around it were fragmented. They’re now coming together as a whole, and that whole complements, and at times runs ahead of, what I focus on at work: observability, accountability, governance and ownership. My rule for all of it: if you can’t see it, you can’t observe it; if you can’t observe it, you can’t measure it; if you can’t measure it, you can’t improve on it; and if you can’t improve on it, you get left behind. Qui non proficit deficit. This post is that rule applied to AI: worry less about the Terminator and more about what we teach the machines, share the responsibility with the labs, and own your data. ...

October 4, 2026 · 11 min · Fabian Williams