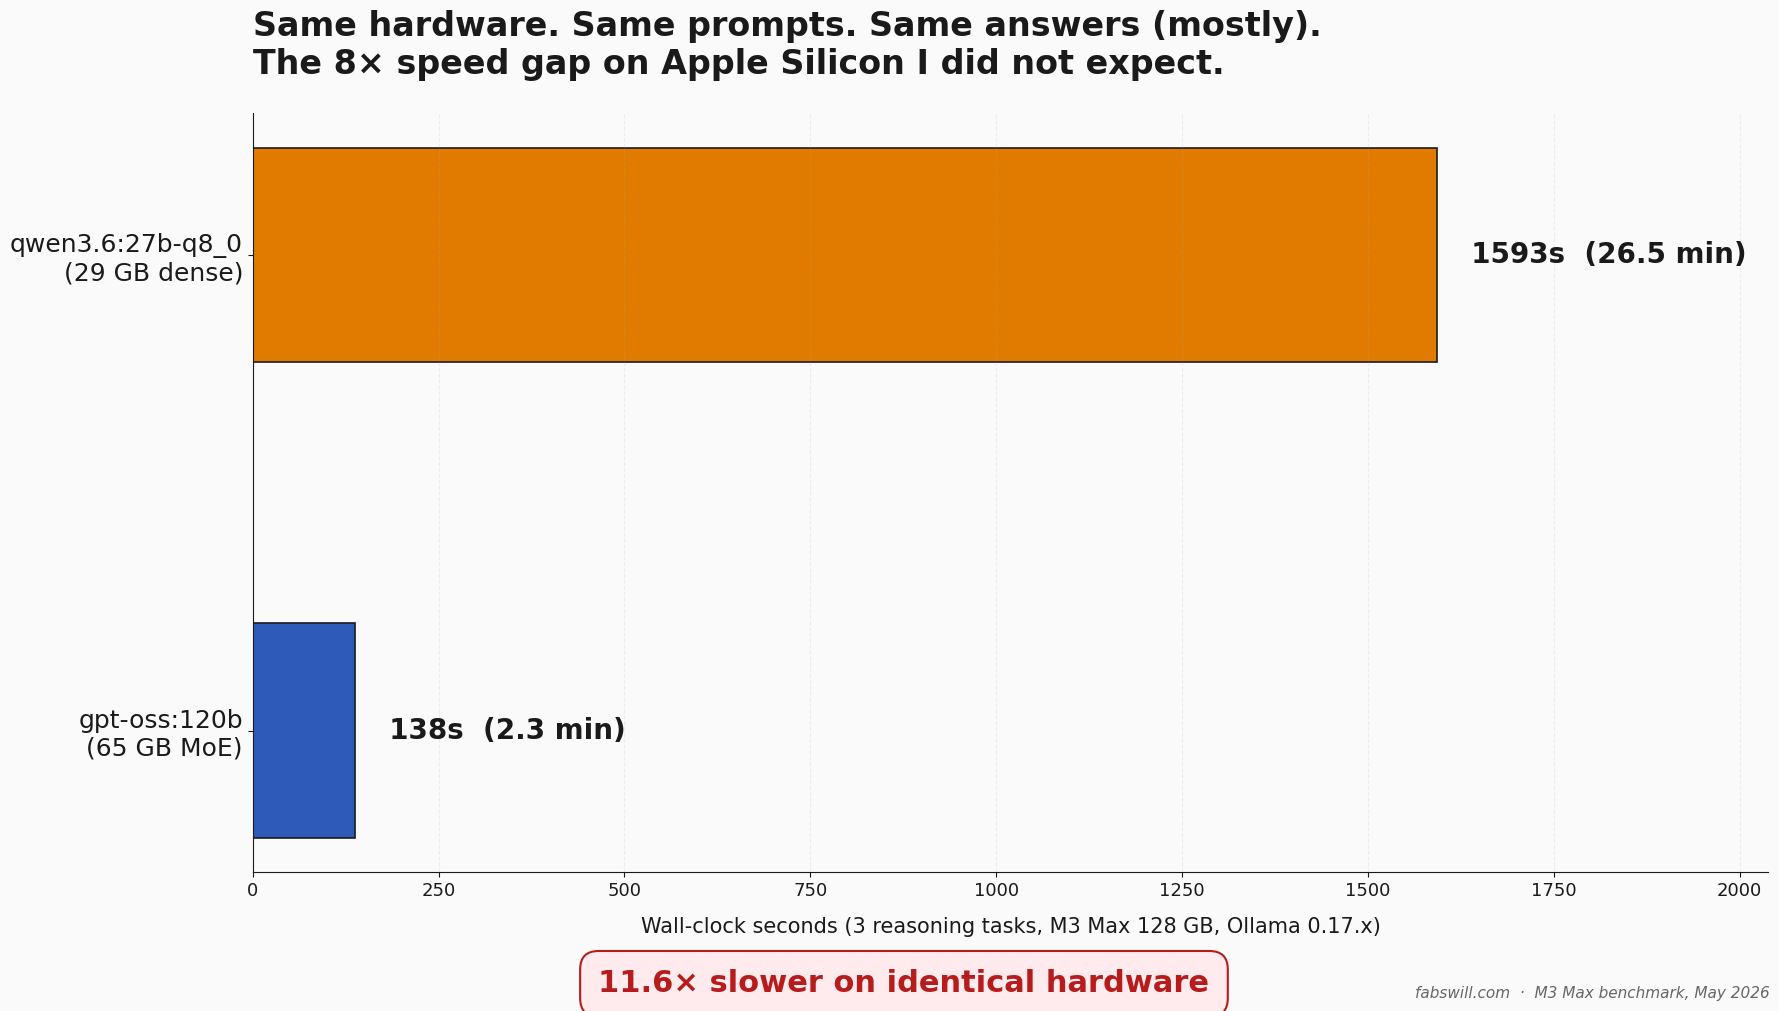
Horizontal bar chart showing gpt-oss:120b at 137 seconds and qwen3.6:27b at 1593 seconds on the same Round 2 reasoning tasks, with an 11.6× slower callout

Qwen 3.6 vs gpt-oss:120b on M3 Max: I Ran a Harder Test, the 8× Speed Gap Surprised Me

TL;DR I published a post last week about replacing gpt-oss:120b with Qwen 3.6 on my MacBook Pro M3 Max. The numbers in that post were real, but one set of tests was structurally gameable — 38 of 40 baseline images were the same class, so an “always-say-A” stub also scored 95 percent. I went back, designed three un-gameable reasoning tasks, and ran them against both local models on identical hardware. gpt-oss:120b finished the three tasks in 137 seconds. qwen3.6:27b-q8_0 took 1593 seconds — 11.6 times slower, on the same M3 Max, for the same prompts and essentially the same answers. This post is the methodology, the receipts, and the honest correction to the migration narrative. ...
May 9, 2026 · 11 min · Fabian Williams
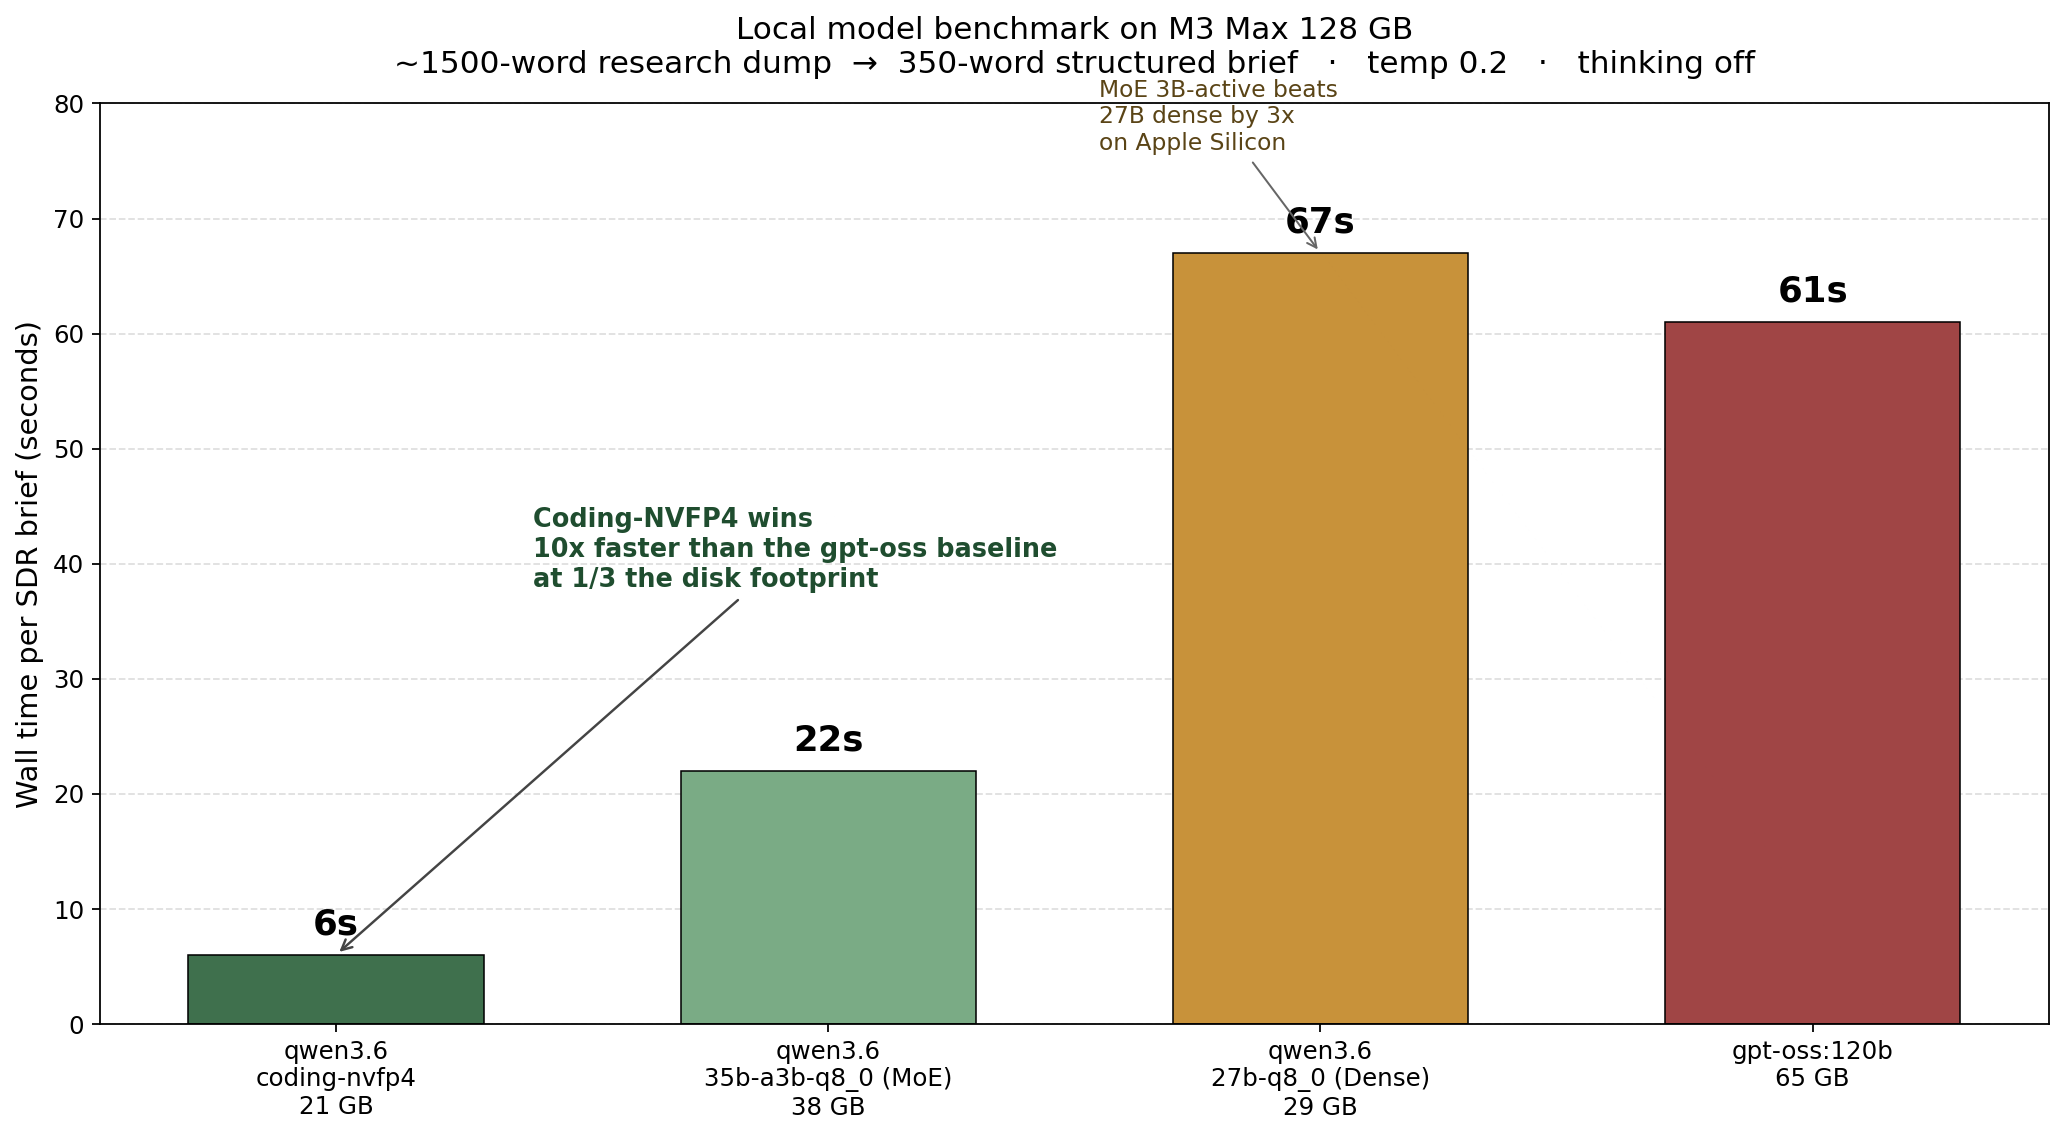
Bar chart comparing wall time of four local models on a structured-output benchmark

Replacing gpt-oss:120b With Qwen3.6 on a MacBook Pro: A Two-Day Local Model Benchmark

TL;DR I spent two days benchmarking three Qwen3.6 variants against gpt-oss:120b on my MacBook Pro M3 Max. The shocking result: a 21 GB coding-tuned model ran an OpenClaw-shaped research-brief workload that I use for the non profit MACONA.org in 6 seconds — 10x faster than gpt-oss:120b on the same prompt. Fast enough that I now have reasonable confidence I could move this kind of work off the SaaS-hosted frontier models I have been paying for and onto local hardware on my dev machine. The deeper finding: the same local model confidently hallucinated a description of an image it could not see, with no error and no warning. Local models are ready for production agent work — at least on hardware like this. Operational asymmetries are real. Verification is not optional. ...

May 2, 2026 · 14 min · Fabian Williams