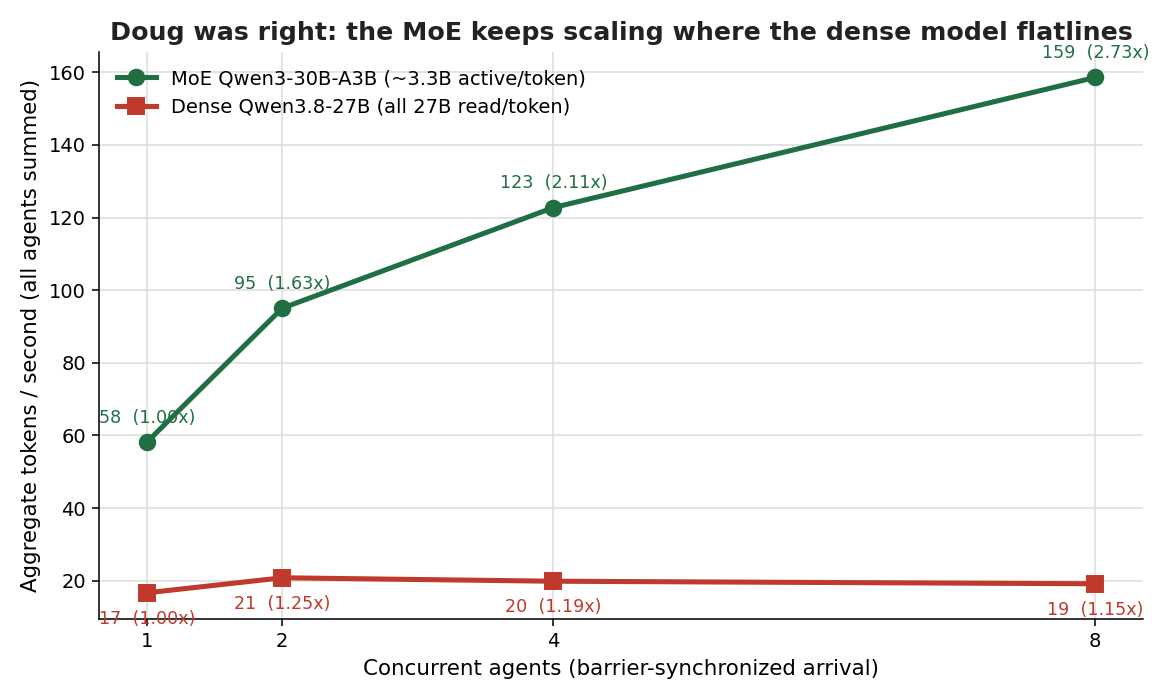
A line chart showing aggregate throughput staying flat near 20 tokens per second on a dense model while a mixture-of-experts model climbs from 58 to 159 tokens per second as concurrent agents rise from one to eight

Doug Was Right: I Swapped In The MoE, And The Concurrency Math Changed

Two days ago I posted 36 barrier-synchronized loads against 1 local model and let the numbers answer a question Reddit handed me. That post ended with a promise. A reader named Doug Ware, who builds applied AI systems for a living, had replied with the one caveat I had not tested, and I said out loud that measuring it was the next thing I would do. This is that measurement. I did not wait, I did not hand-wave it, and I kept every honest asterisk in. ...
August 20, 2026 · 9 min · Fabian Williams
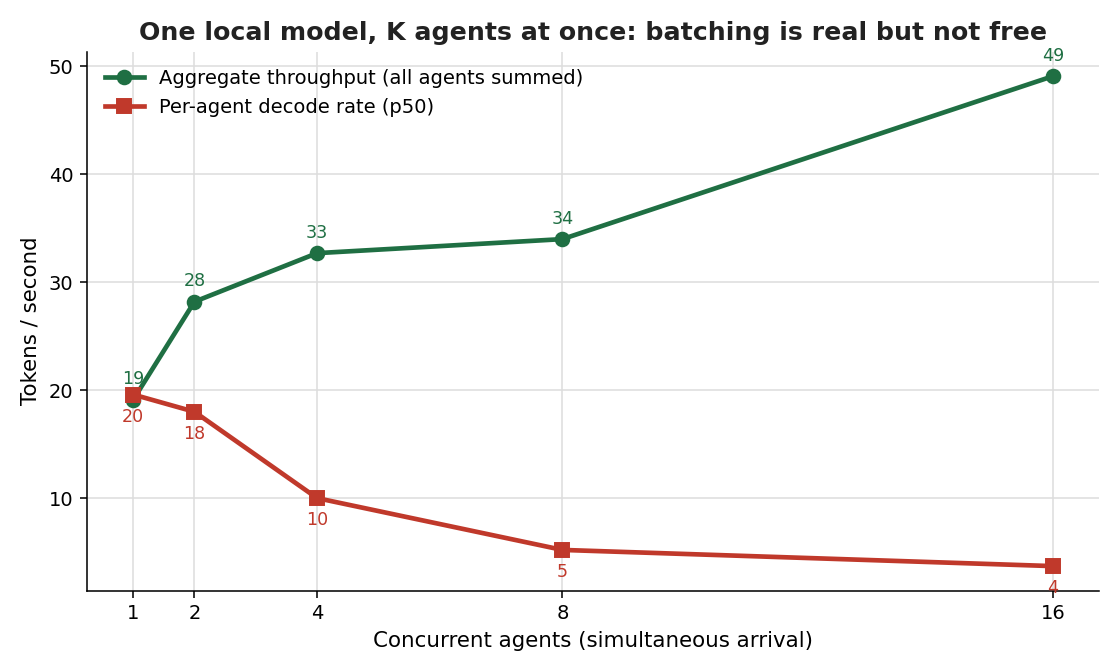
A line chart showing aggregate throughput flattening while per-agent decode rate collapses as concurrent agents rise from one to eight on one local MLX model

You Asked, So I Measured: What Concurrency Actually Costs On One Local Model

Over last week and these last 2 days in this week I posted measured answers to readers both in Twitter and Reddit who asked whether my experiments of 2 local agents on 1 Mac run in parallel or take turns. The answers was that they share one continuous batch, batching is real, and 3 quiet choices collapse it. I thought that was the end of it. It was not. The comments were better than my post, WHICH IS AWESOME, becaue this is the crowdsourcing of brain power I love. I not trying to be a KNOW IT ALL Im trying to be a LEARN IT ALL! ...

August 18, 2026 · 14 min · Fabian Williams
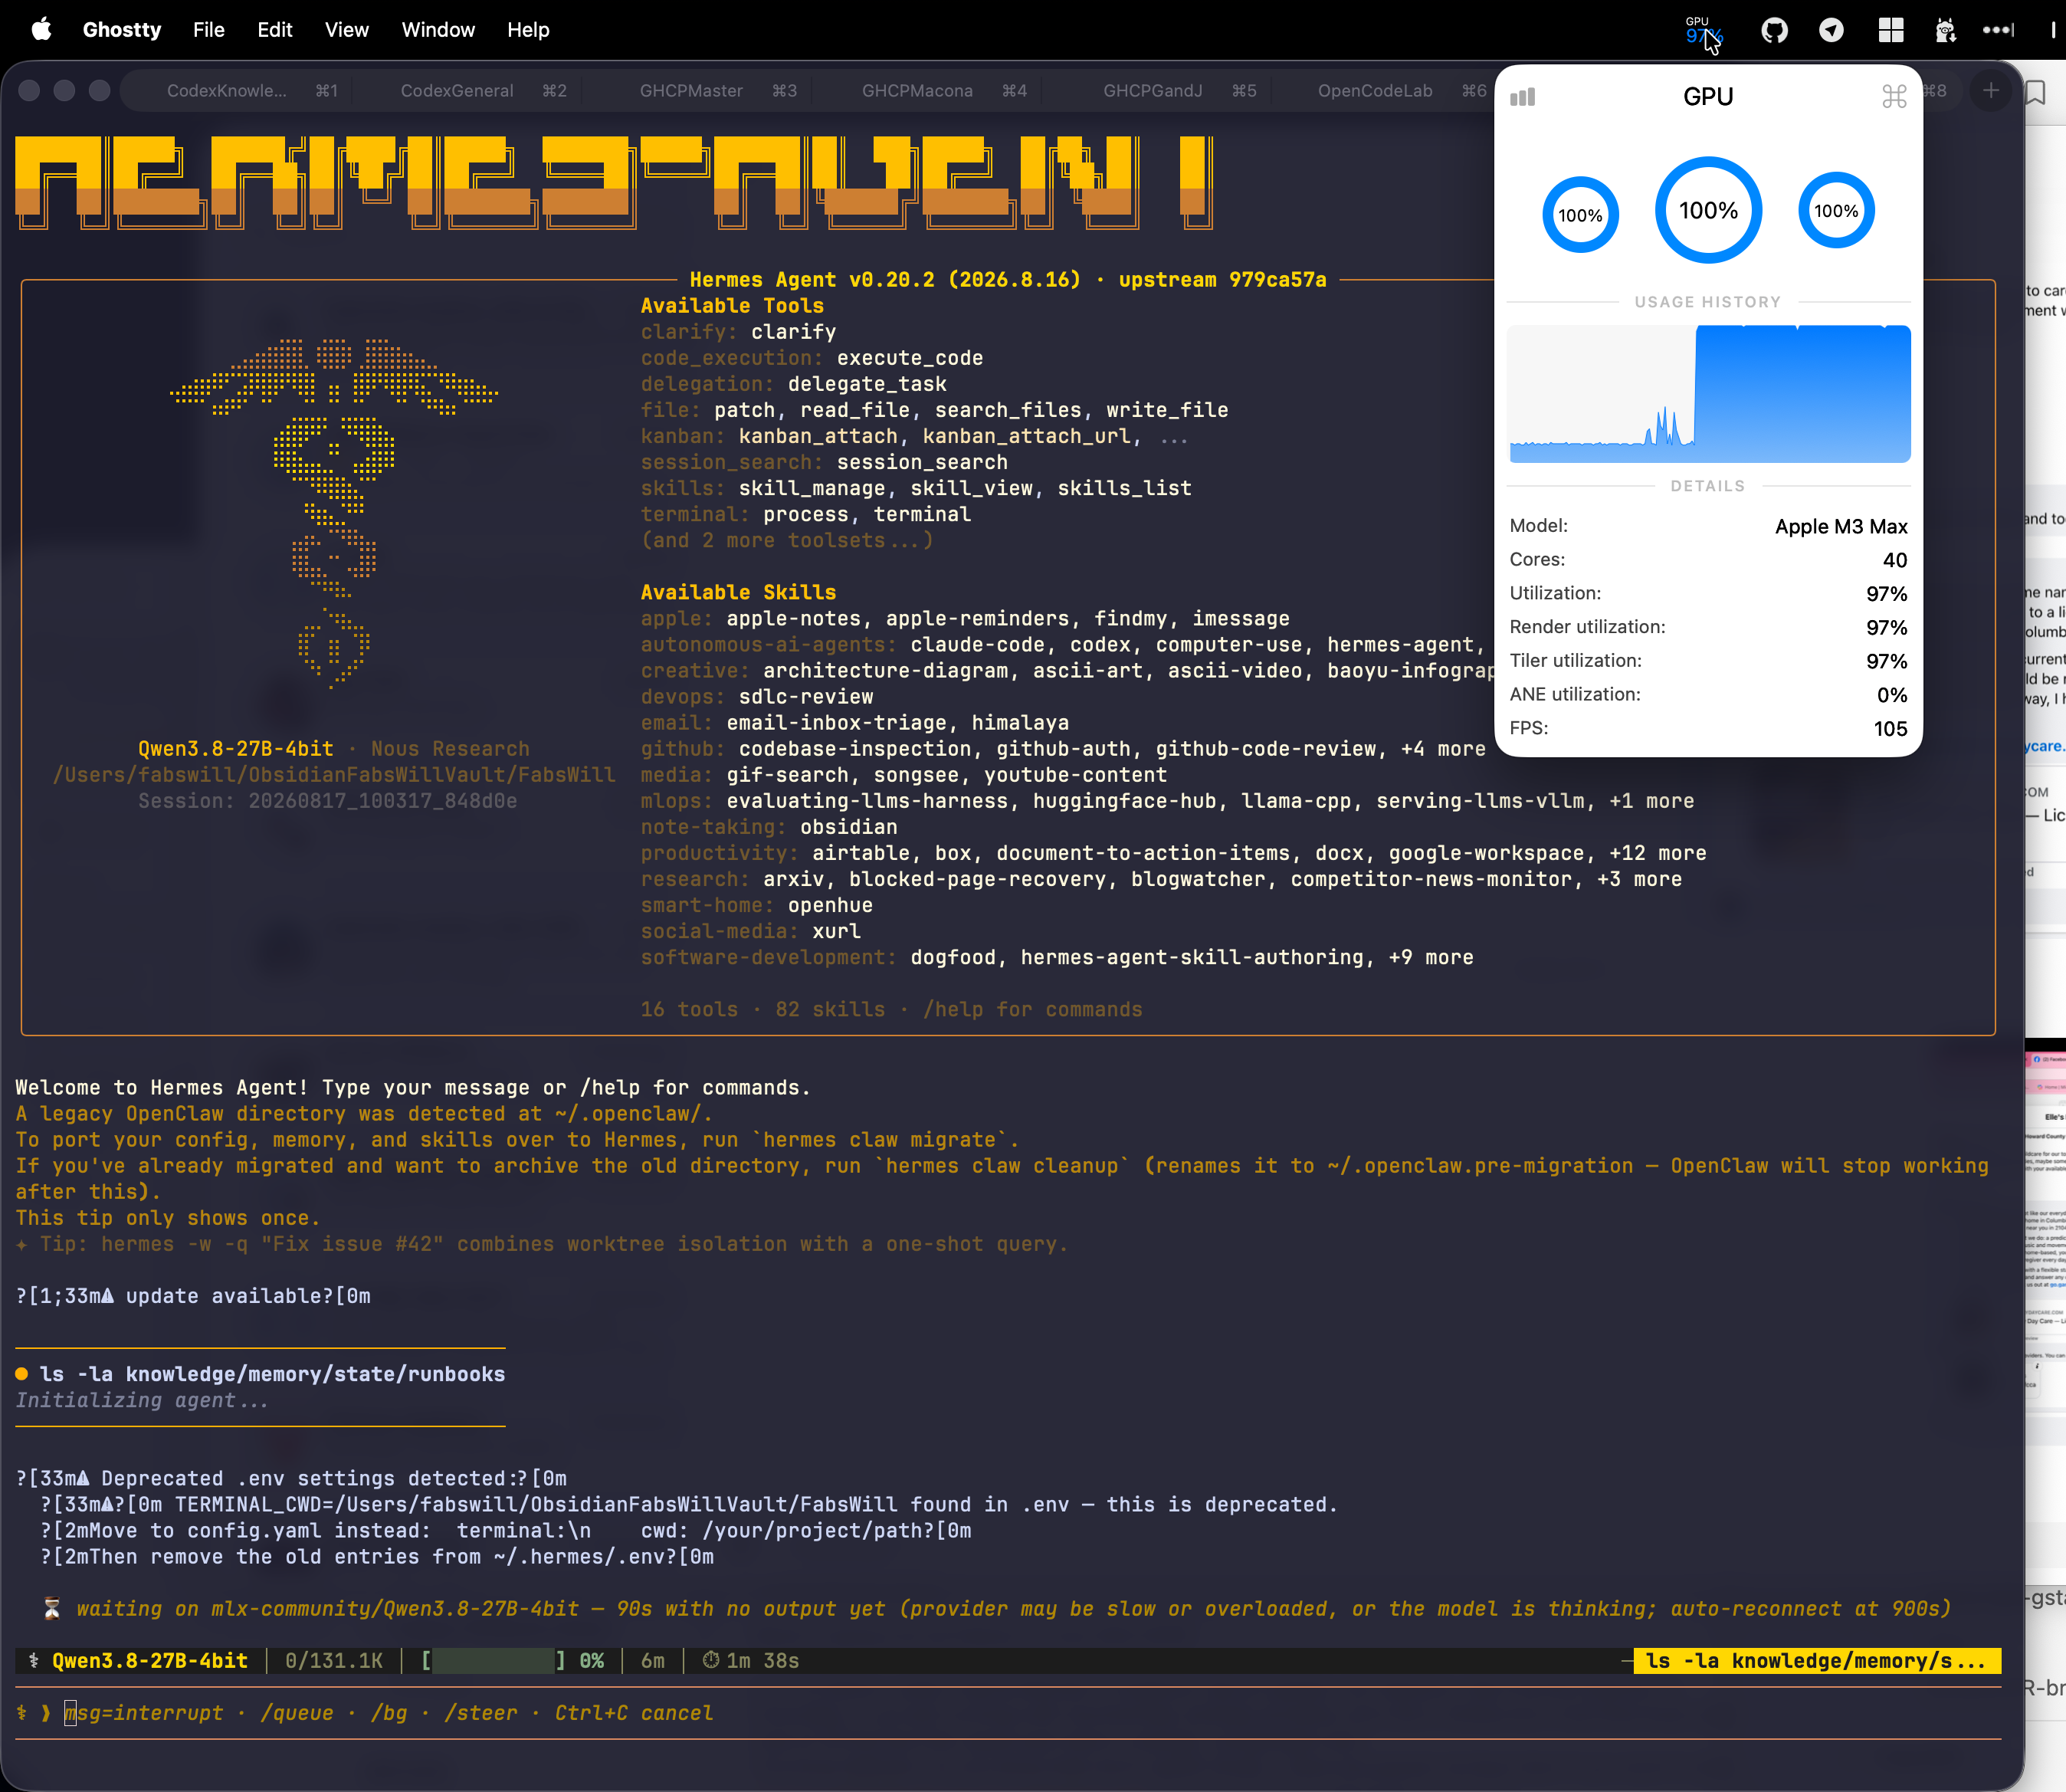
The Hermes agent running against a local Qwen3.8-27B MLX server, with the Apple M3 Max GPU pinned at 97 percent on the first turn

I Added a Second Local Agent This Week. Here Is the Receipt for Every Human Decision Behind It.

This week I trialed a second local coding agent, Hermes from Nous Research, on my own MacBook Pro M3 Max, pointed at the same local Qwen 3.8 model I already run. I installed it additively, so nothing already working could break, governed it with manual approvals, and did not stop until it proved it behaves. Here is the trial, in tables and screenshots. One housekeeping note before the story. Last week’s post got called AI slop on Reddit. My full answer to that, and the standing standard I now hold my writing to, lives on its own page: On Slop, And Who Gets To Call It That. It is not the point of this post, so I moved it out of the way. Back to Hermes. ...

August 17, 2026 · 7 min · Fabian Williams
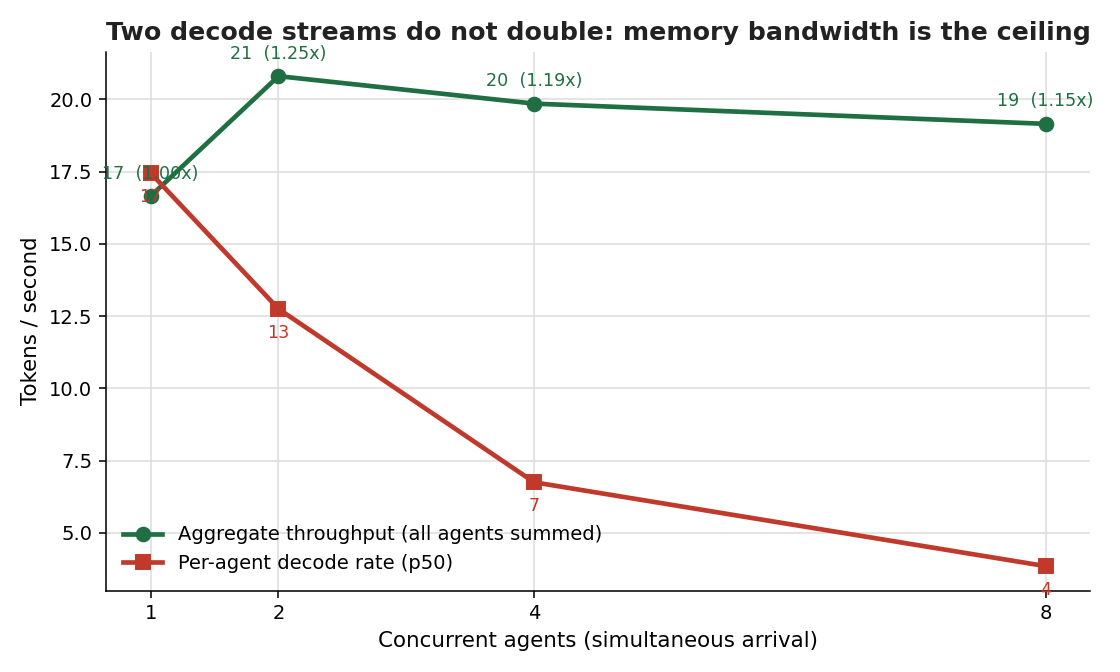
A line chart showing aggregate throughput rising with concurrent agents while per-agent decode rate falls, on one local MLX model

Two Agents, One Local Model: Do They Run in Parallel, or Take Turns? I Measured It.

A reader on Reddit asked me a sharp question about my last post. I had trialed a second local coding agent, Hermes, pointed at the same local Qwen 3.8 model my other agent already uses. His question was simple. Did I ever run both agents at the same time, two separate harnesses hammering one model on one Mac at once. And what about Hermes spawning its own sub-agents against that same endpoint. Is any of that predictable. ...

August 17, 2026 · 9 min · Fabian Williams