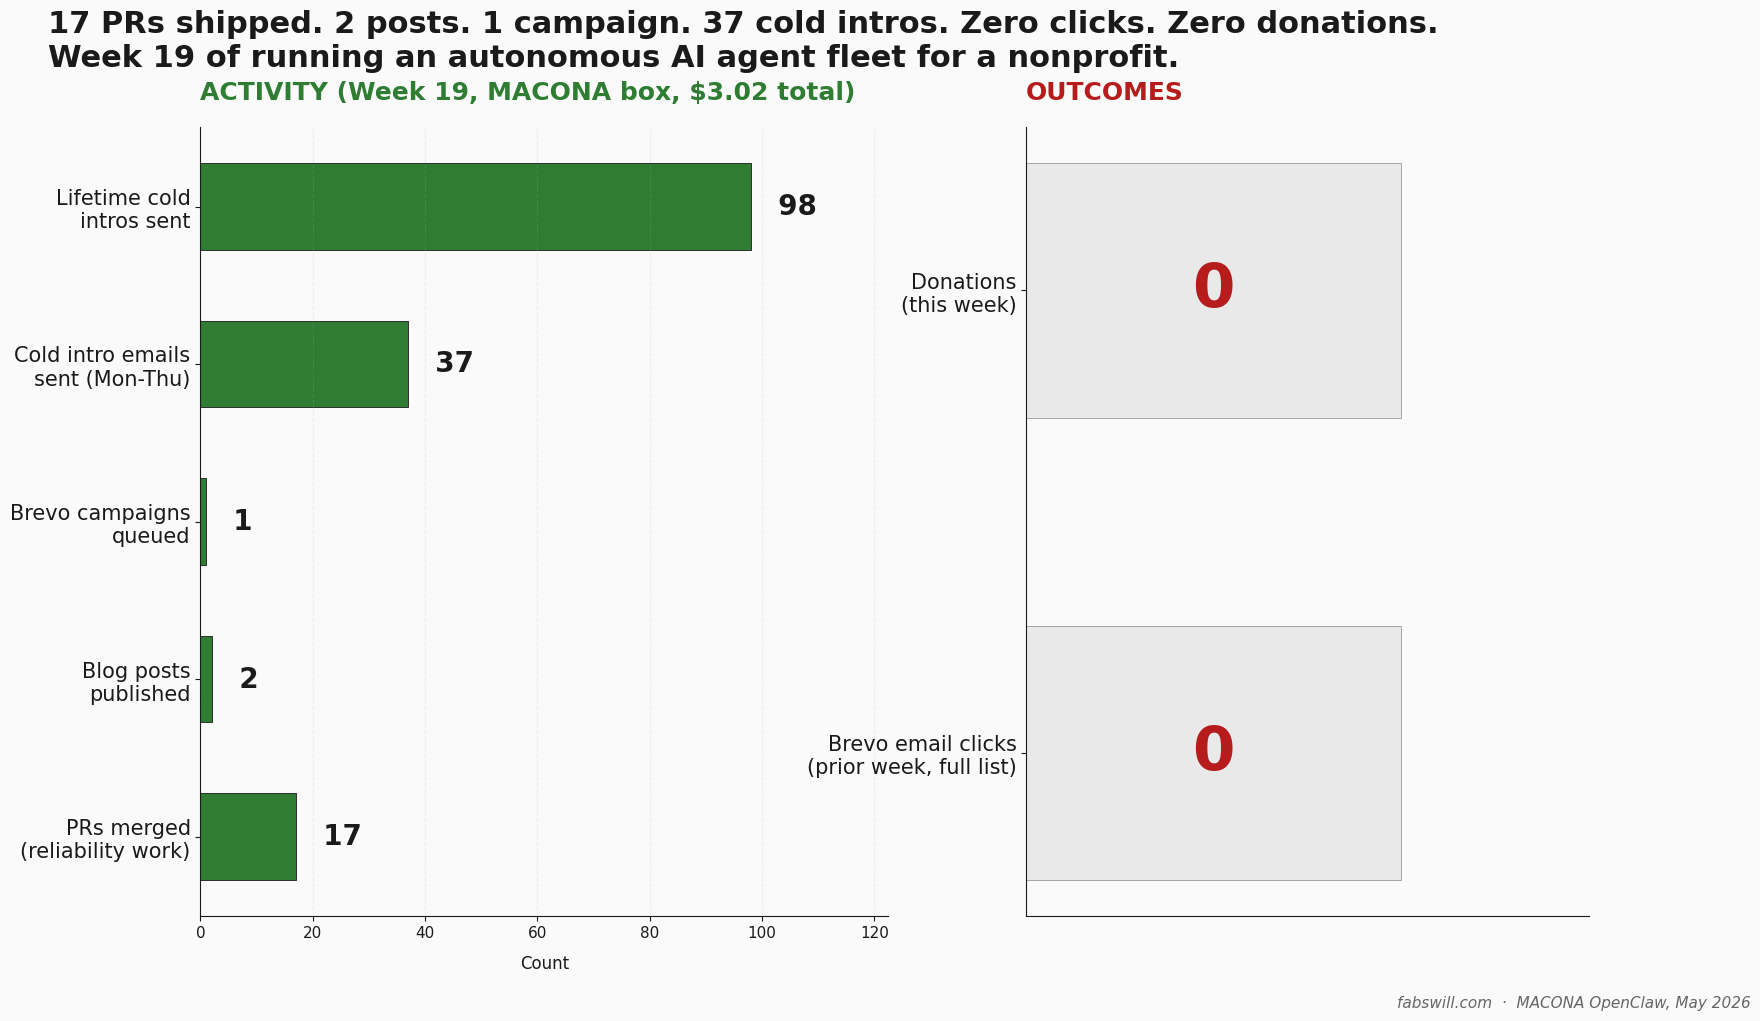
Two-panel chart: left shows 17 PRs, 2 blog posts, 1 campaign, 37 cold intros, 98 lifetime intros shipped in green; right shows zero human clicks and zero donations in red

The AI Agent Fleet Works. The Trust Funnel Does Not.

TL;DR I volunteer with MACONA, a 501(c)(3) nonprofit that ships food, medicine, feminine hygiene products, donated computers, and clothing to communities and schools in West Africa. For a few few monthis now I have run a small autonomous AI agent fleet for the organization: five named agents, cron-driven, running through OpenClaw on a simple Windows box. Week 19 (I track progress via week numbers for me and my Agents) looked like a win on every internal activity metric: 17 reliability PRs merged, 2 awareness-day blog posts published, 1 Brevo campaign queued, and 37 cold introduction emails sent. ...
May 11, 2026 · 14 min · Fabian Williams
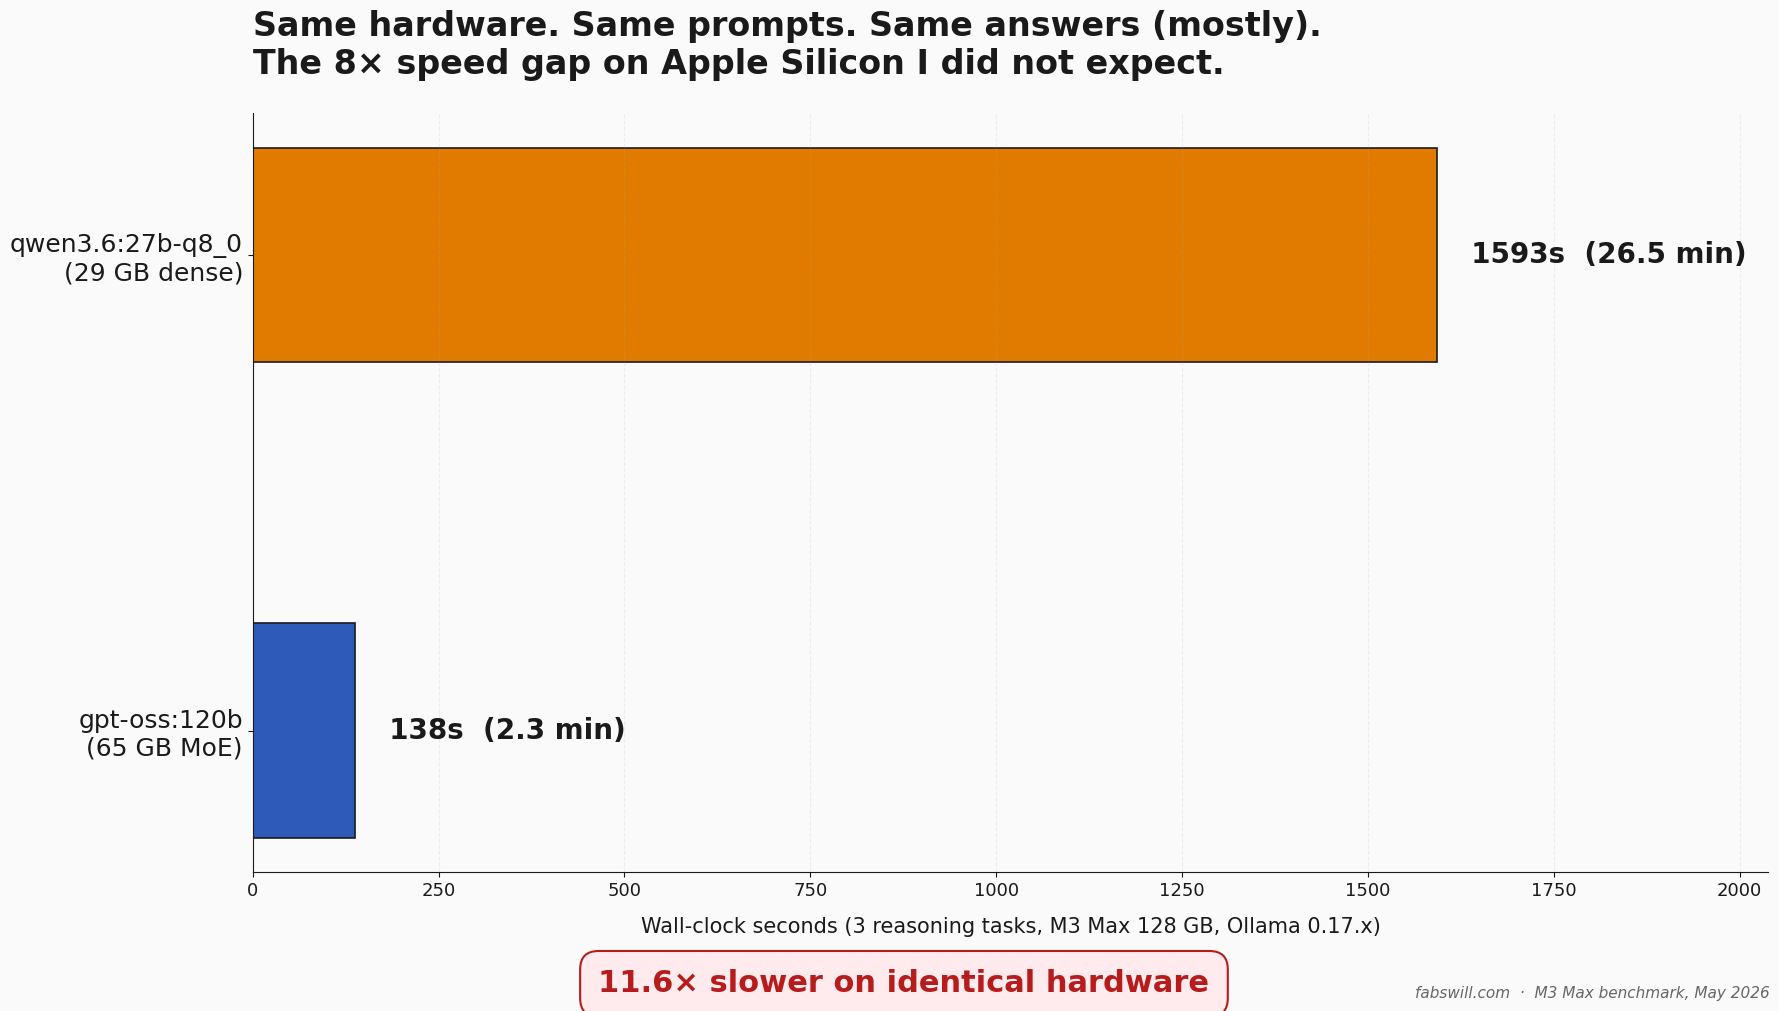
Horizontal bar chart showing gpt-oss:120b at 137 seconds and qwen3.6:27b at 1593 seconds on the same Round 2 reasoning tasks, with an 11.6× slower callout

Qwen 3.6 vs gpt-oss:120b on M3 Max: I Ran a Harder Test, the 8× Speed Gap Surprised Me

TL;DR I published a post last week about replacing gpt-oss:120b with Qwen 3.6 on my MacBook Pro M3 Max. The numbers in that post were real, but one set of tests was structurally gameable — 38 of 40 baseline images were the same class, so an “always-say-A” stub also scored 95 percent. I went back, designed three un-gameable reasoning tasks, and ran them against both local models on identical hardware. gpt-oss:120b finished the three tasks in 137 seconds. qwen3.6:27b-q8_0 took 1593 seconds — 11.6 times slower, on the same M3 Max, for the same prompts and essentially the same answers. This post is the methodology, the receipts, and the honest correction to the migration narrative. ...

May 9, 2026 · 11 min · Fabian Williams
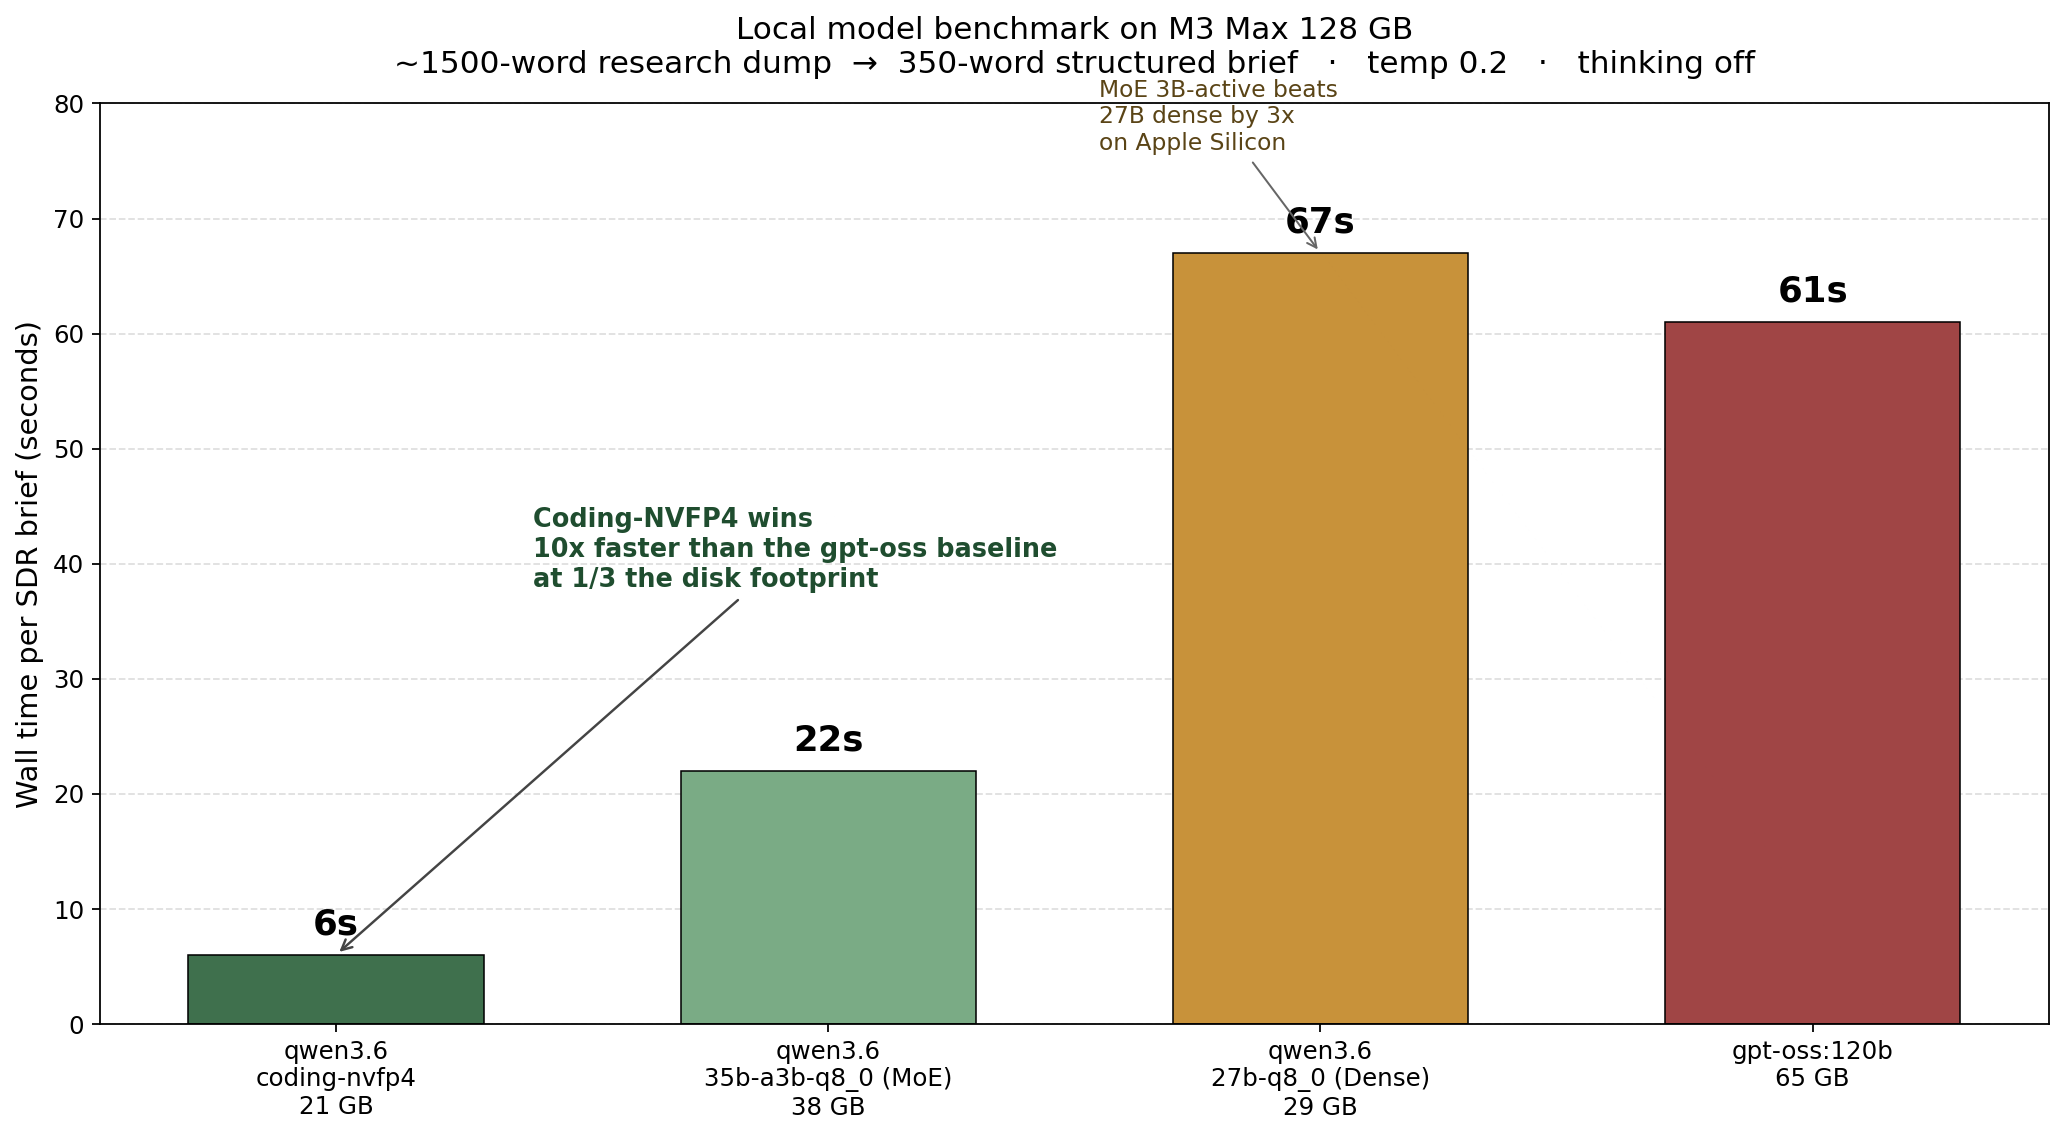
Bar chart comparing wall time of four local models on a structured-output benchmark

Replacing gpt-oss:120b With Qwen3.6 on a MacBook Pro: A Two-Day Local Model Benchmark

TL;DR I spent two days benchmarking three Qwen3.6 variants against gpt-oss:120b on my MacBook Pro M3 Max. The shocking result: a 21 GB coding-tuned model ran an OpenClaw-shaped research-brief workload that I use for the non profit MACONA.org in 6 seconds — 10x faster than gpt-oss:120b on the same prompt. Fast enough that I now have reasonable confidence I could move this kind of work off the SaaS-hosted frontier models I have been paying for and onto local hardware on my dev machine. The deeper finding: the same local model confidently hallucinated a description of an image it could not see, with no error and no warning. Local models are ready for production agent work — at least on hardware like this. Operational asymmetries are real. Verification is not optional. ...

May 2, 2026 · 14 min · Fabian Williams
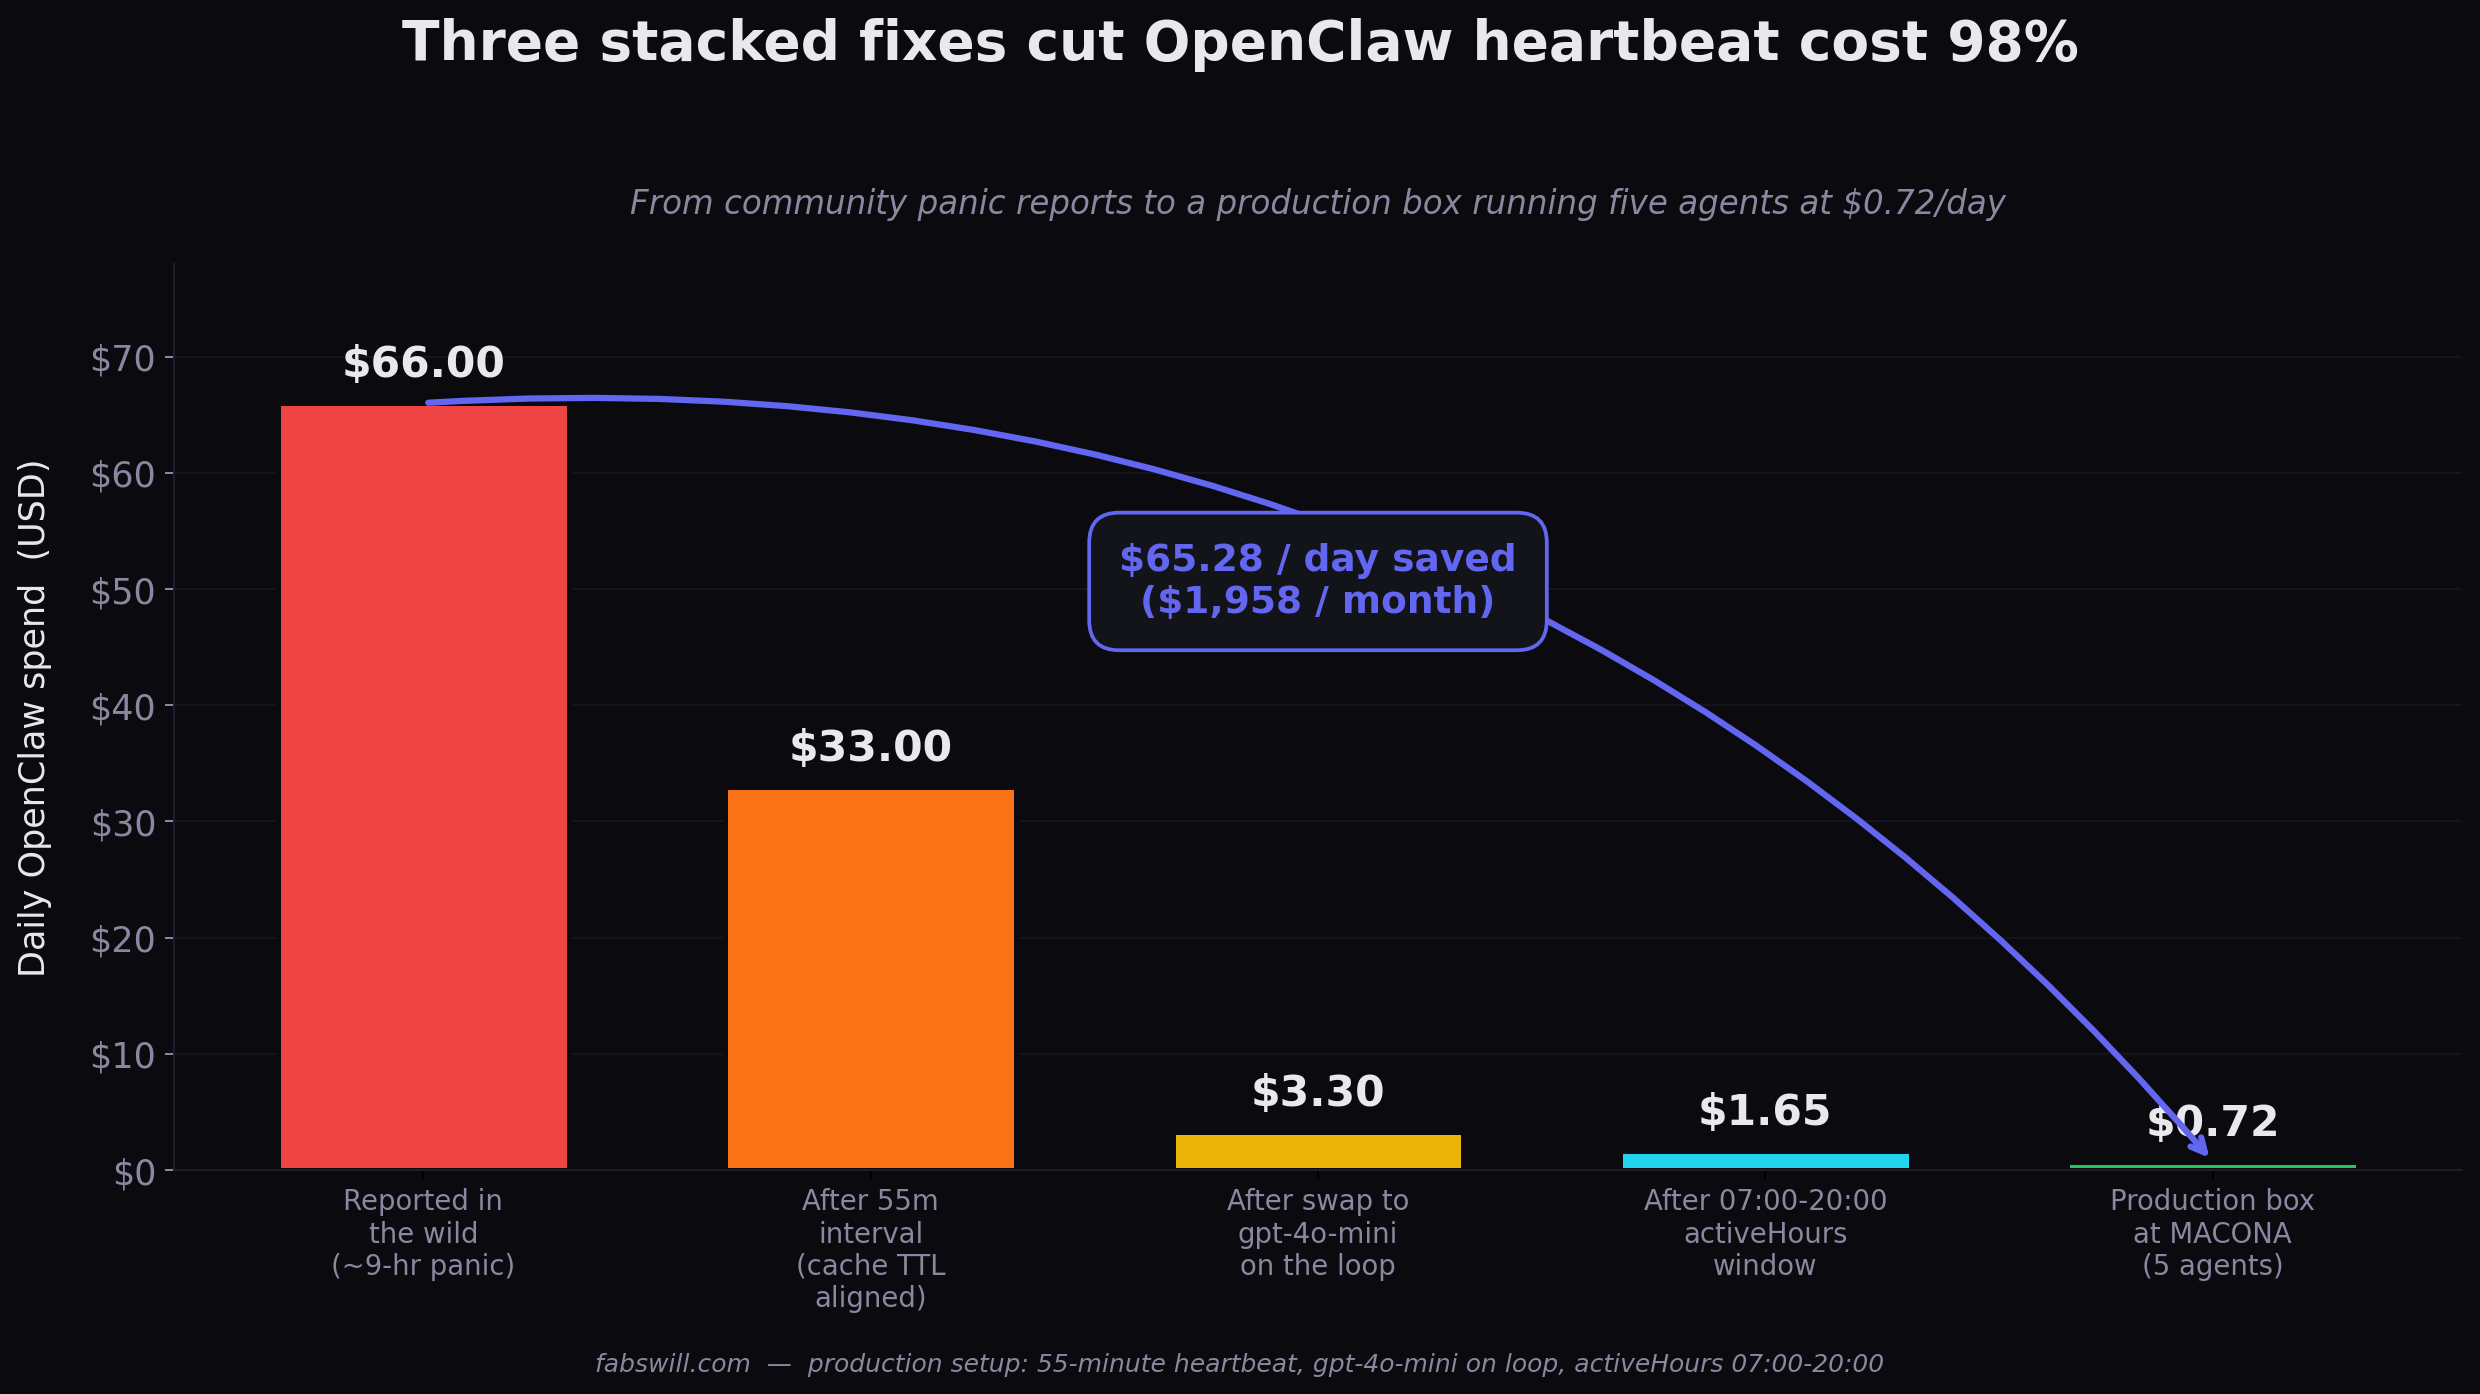
Waterfall chart showing OpenClaw heartbeat daily cost dropping from $66 to $0.72 after three stacked config fixes

I Run Five OpenClaw Agents for 72 Cents a Day

TL;DR Five OpenClaw agents run the content and executive-assistant pipeline for MACONA — a nonprofit I volunteer with — at $0.72 a day. The most common support question on r/OpenClaw is “$25 in 9 hours, help.” The gap between those two numbers is three config decisions stacked on top of each other: heartbeat interval, model on the loop, and hours of operation. None of them are clever. All of them are usually set wrong by default. ...

April 22, 2026 · 8 min · Fabian Williams
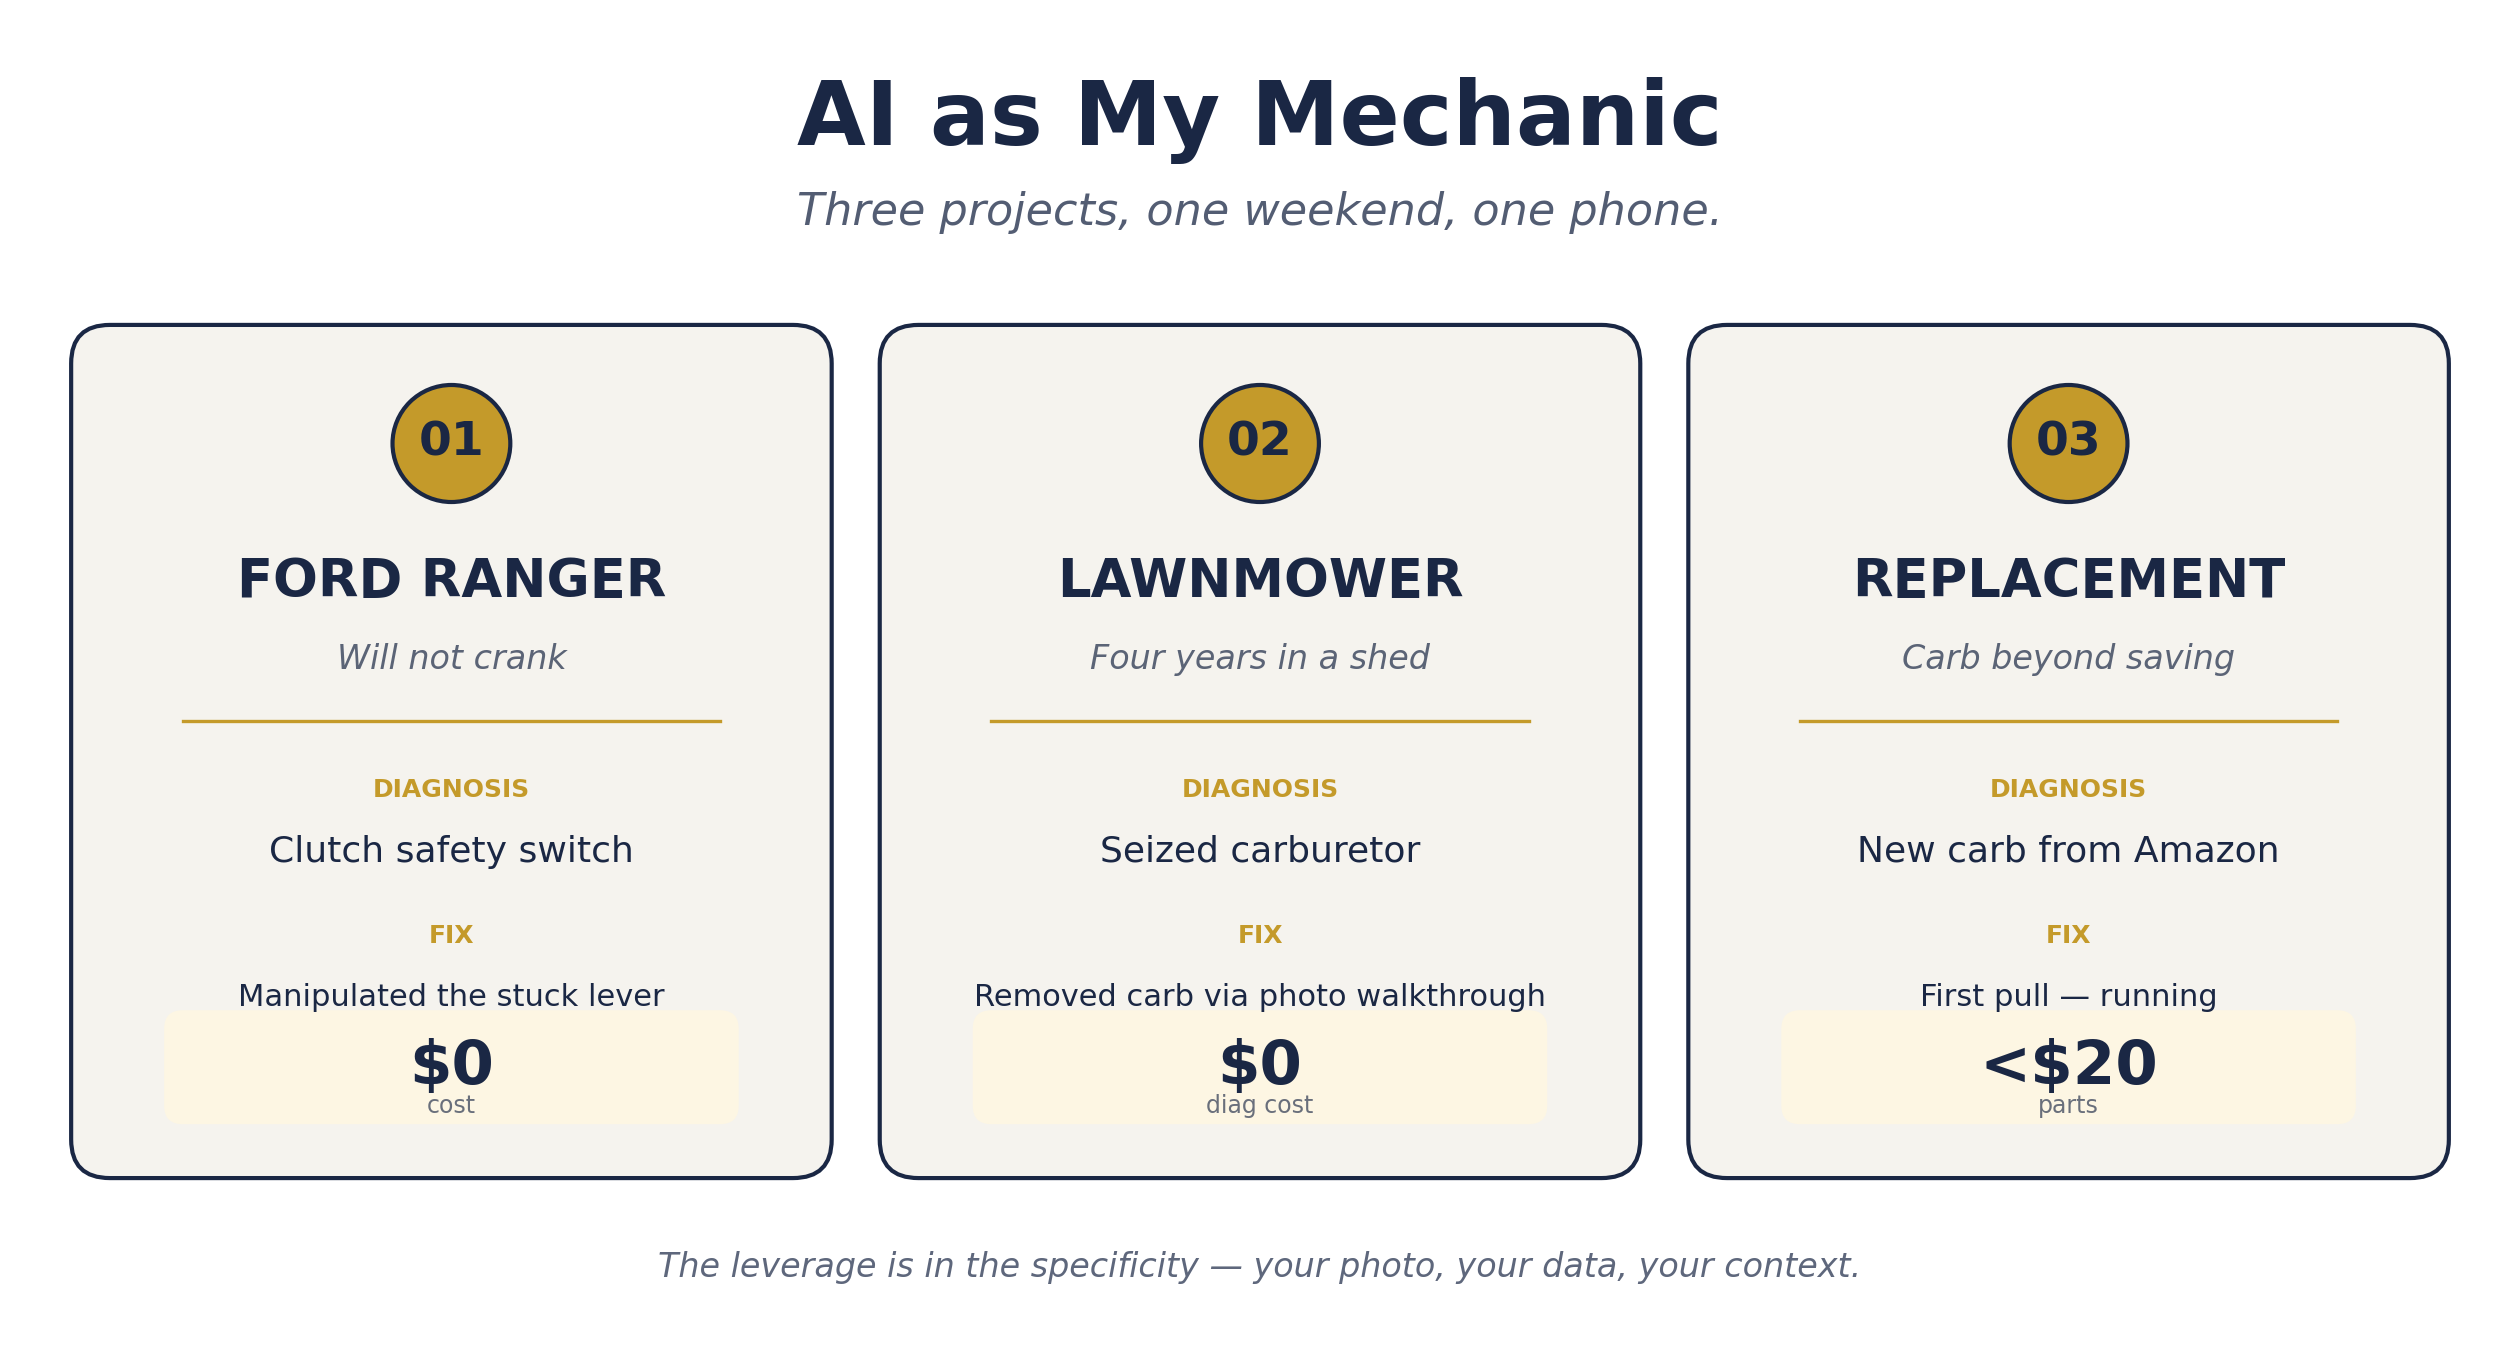
Three mechanical projects fixed with AI over one weekend — Ford Ranger, lawnmower carb removal, lawnmower replacement

AI Boosted My Mechanical Engineering Muscle

TL;DR Over one weekend I fixed a 2001 Ford Ranger that would not crank and a lawnmower that had been sitting in a shed for four years. The truck turned out to be a stuck clutch safety switch — cost, zero. The lawnmower needed a replacement carburetor from Amazon for under twenty dollars. I am not a mechanic. ChatGPT was my shop manual, and the whole thing was driven by photos of my actual parts, not generic internet tutorials. ...

April 19, 2026 · 5 min · Fabian Williams
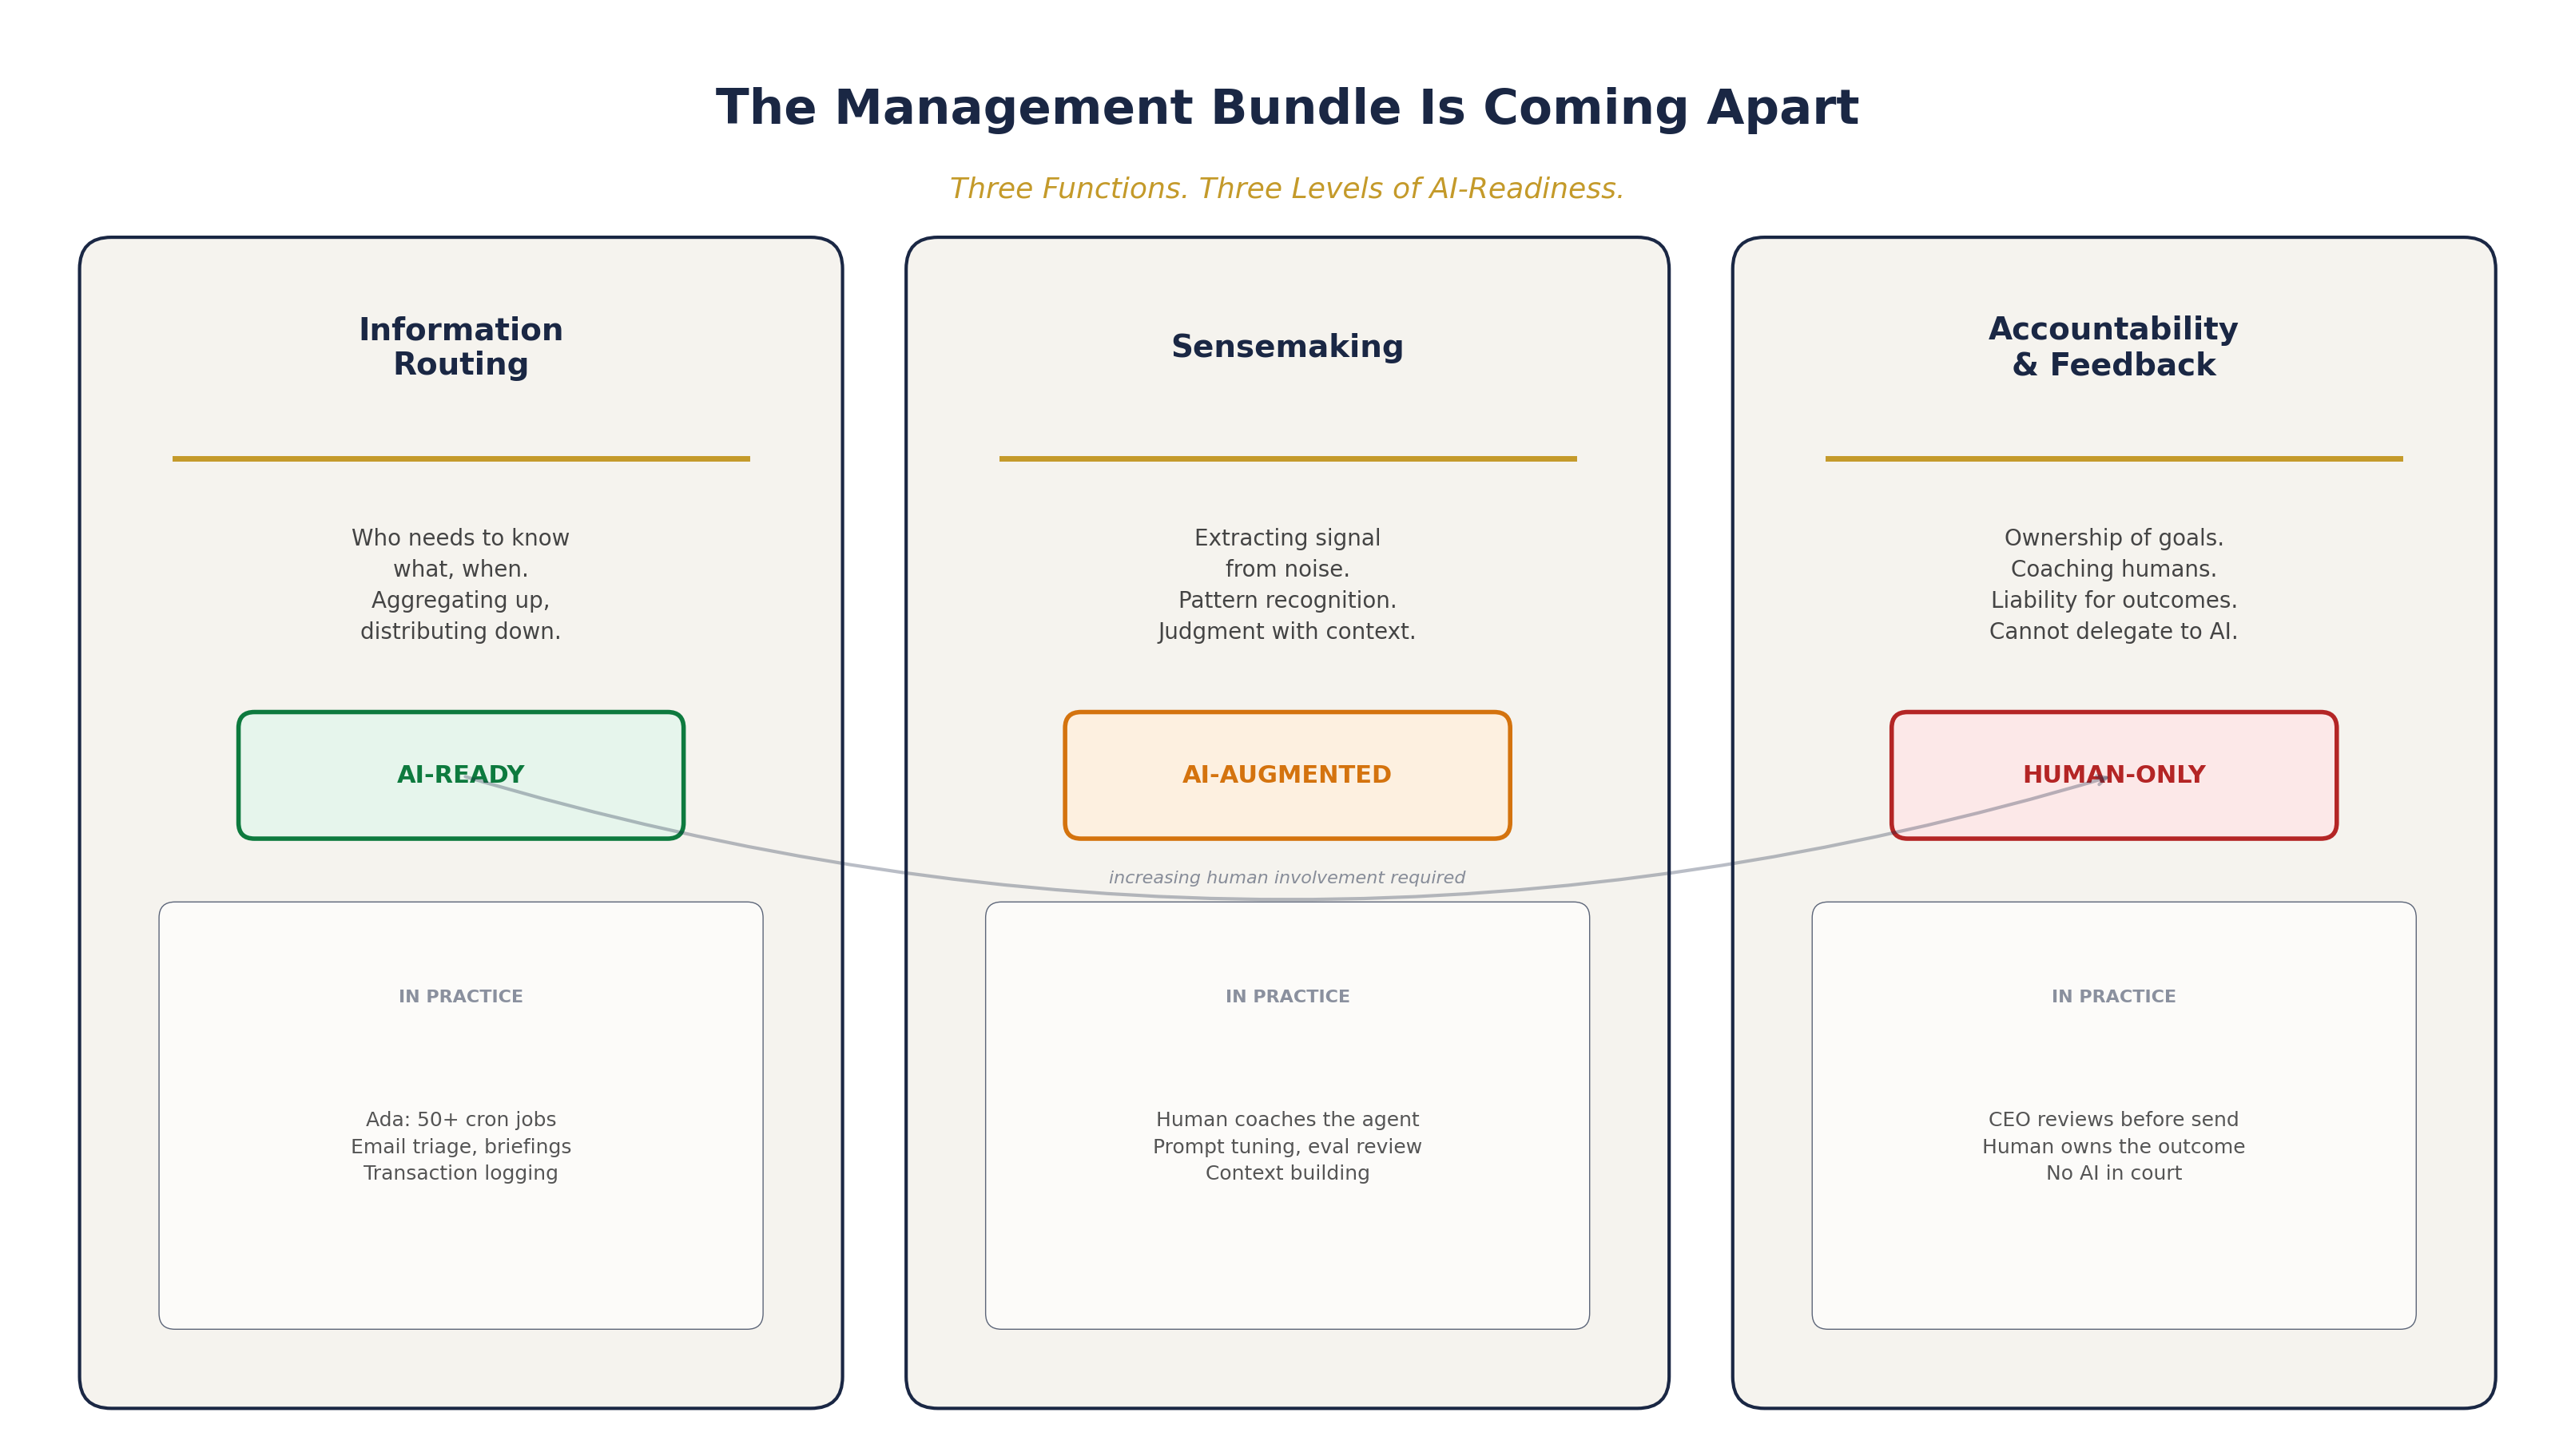
Three pillars of management unbundling — Information Routing (AI-Ready), Sensemaking (AI-Augmented), Accountability (Human-Only)

PM Life as Agents Take on More

TL;DR I had a sidewalk conversation with two neighbors that turned into a real-time debate about AI replacing jobs. Then I watched a Nate video that gave me the exact framework to explain why all 3 were right — and wrong. One neighbor is a project manager already using AI daily. One is a business analyst who coaches companies. One of my neighbours’ husband — a skeptic — is convinced AI cannot do creative work. All 3 are right in their position, and also all of us wrong, depending on which management function you are talking about. ...

April 12, 2026 · 9 min · Fabian Williams
Split illustration showing a human brain with fading neural pathways alongside an AI circuit board with data streams — bridging biological and digital memory

Your Brain Forgets Most of Your Life. So Does Your AI Agent.

TL;DR Neuroscientist Lisa Genova explains why forgetting is normal — your brain filters out most of your day, loses context when you change rooms, and is terrible at remembering future intentions. I watched her TED talk and realized I had already encountered every one of these failures in AI agents I build for real organizations. Here is how the parallels work, what breaks in production, and what I built to fix it. ...

April 12, 2026 · 11 min · Fabian Williams
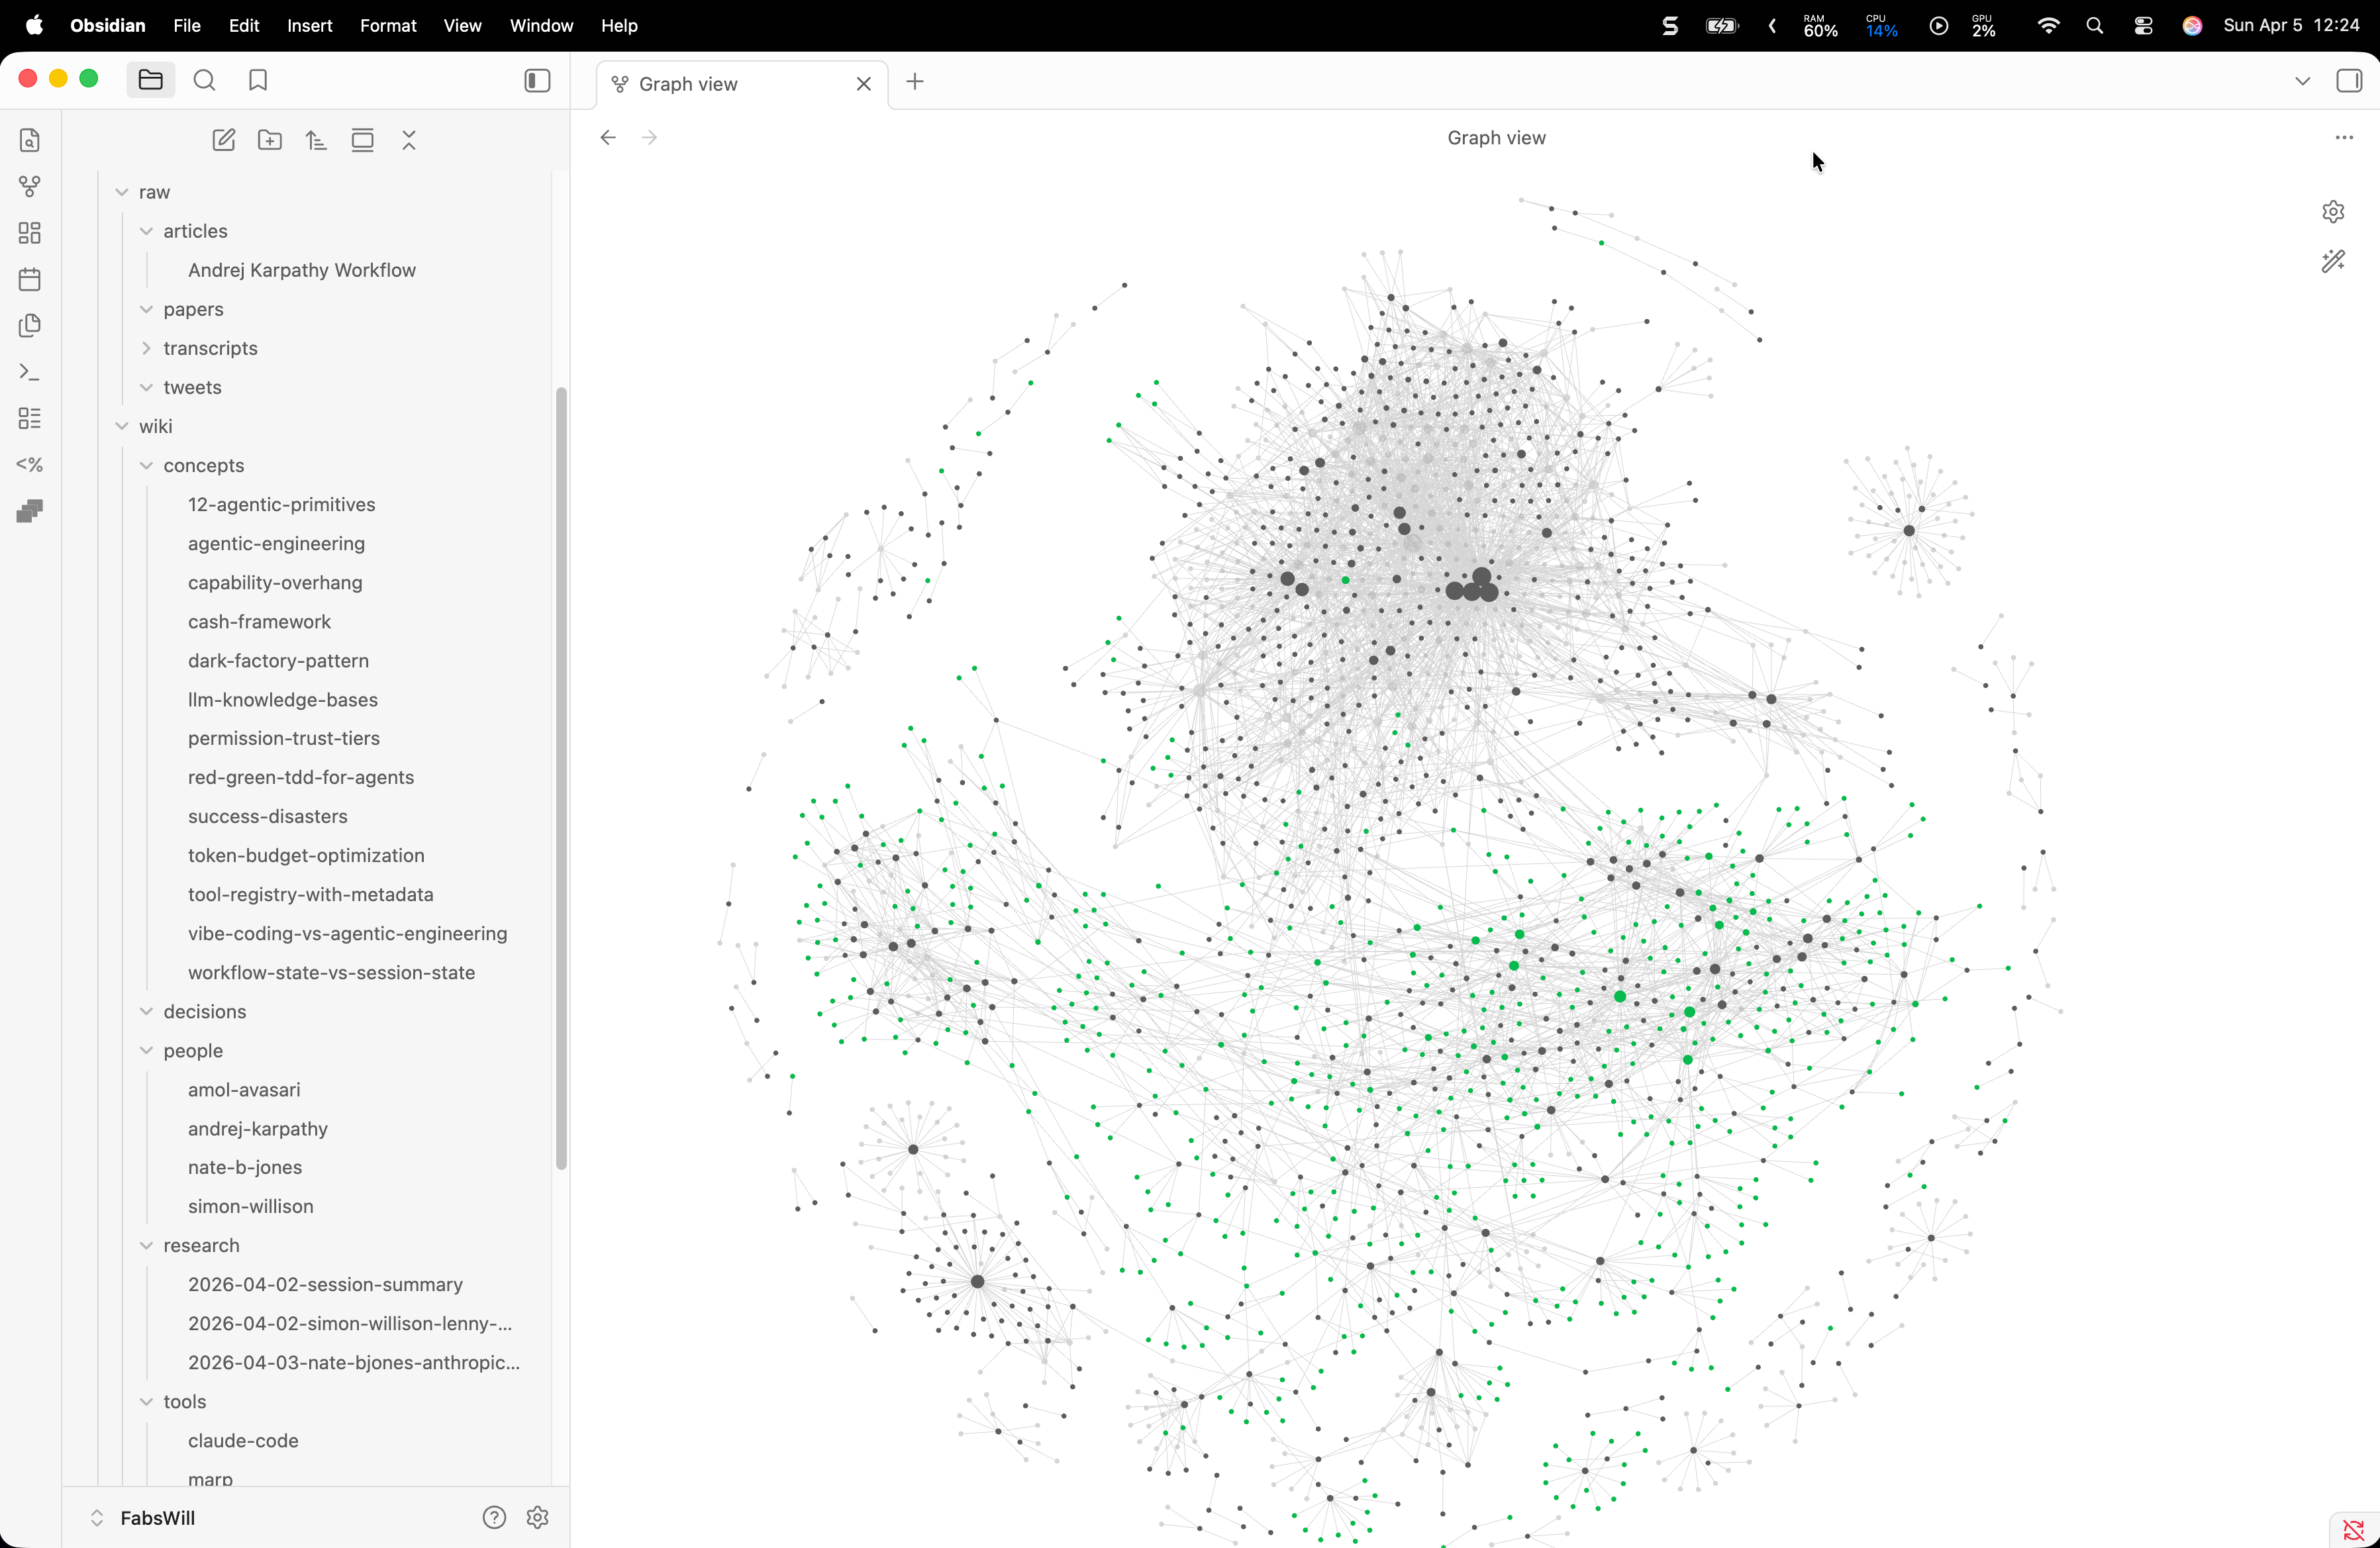
Obsidian graph view showing 21 cross-linked wiki articles compiled by Claude Code from raw transcripts

I Built a Knowledge Base That Writes Itself. Here Is What Andrej Karpathy Got Right.

TL;DR Andrej Karpathy tweeted about using LLMs to build personal knowledge bases — raw sources in, compiled wiki out, all in Obsidian. I implemented his entire workflow in one session using Claude Code skills. Four YouTube transcripts became 21 cross-linked wiki articles. The system now compiles new sources, health-checks its own consistency, and searches itself. It took an afternoon. It will compound forever. Your AI should not just answer questions. It should build a knowledge base that makes every future question easier to answer. ...

April 5, 2026 · 8 min · Fabian Williams
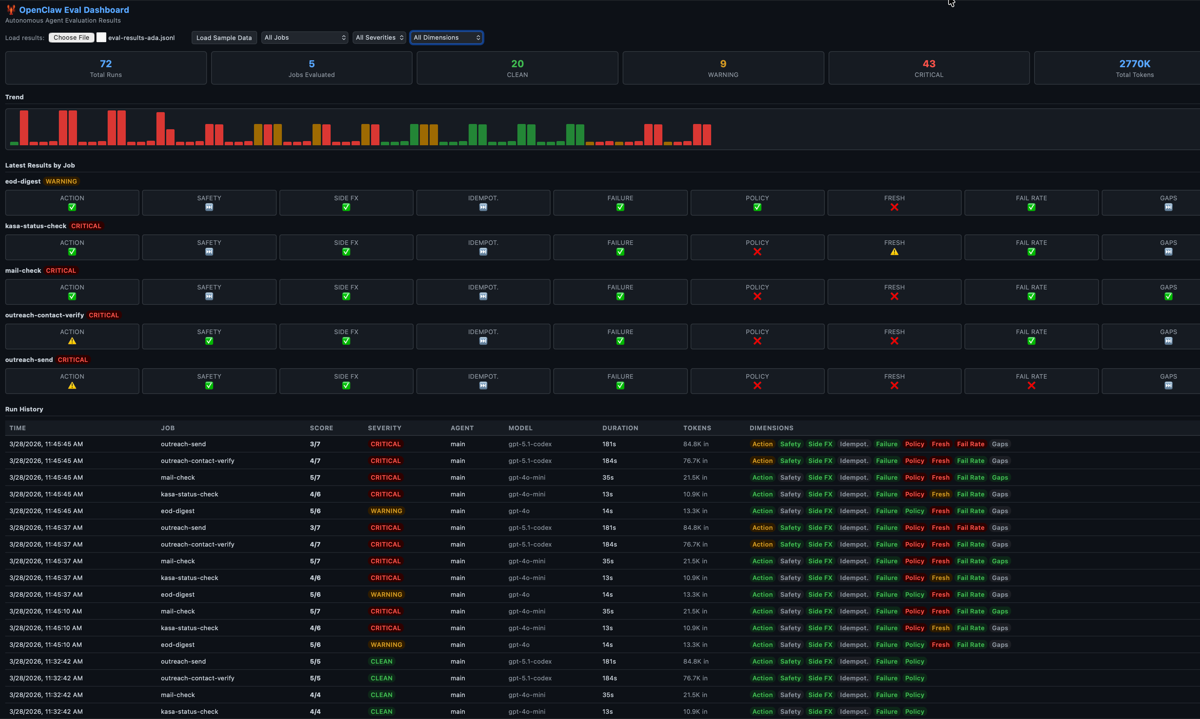
OpenClaw Eval Dashboard showing mixed results across 9 dimensions — the honest picture after adding freshness, failure rate, and delivery gap scoring

How Do You Trust an Autonomous AI Agent? Evals Are the Answer.

TL;DR I run an autonomous AI agent on a Mac Mini in my house. She handles 16 daily cron jobs — finances, email triage, outreach campaigns, device monitoring, morning briefings. The agent says “done.” But did it actually do anything? I built a 9-dimension eval rubric to find out. Along the way I discovered that my evals were broken, my agent was better than I thought, and the most important metric isn’t pass/fail — it’s whether a failure is your fault or the agent’s fault. ...

March 28, 2026 · 10 min · Fabian Williams
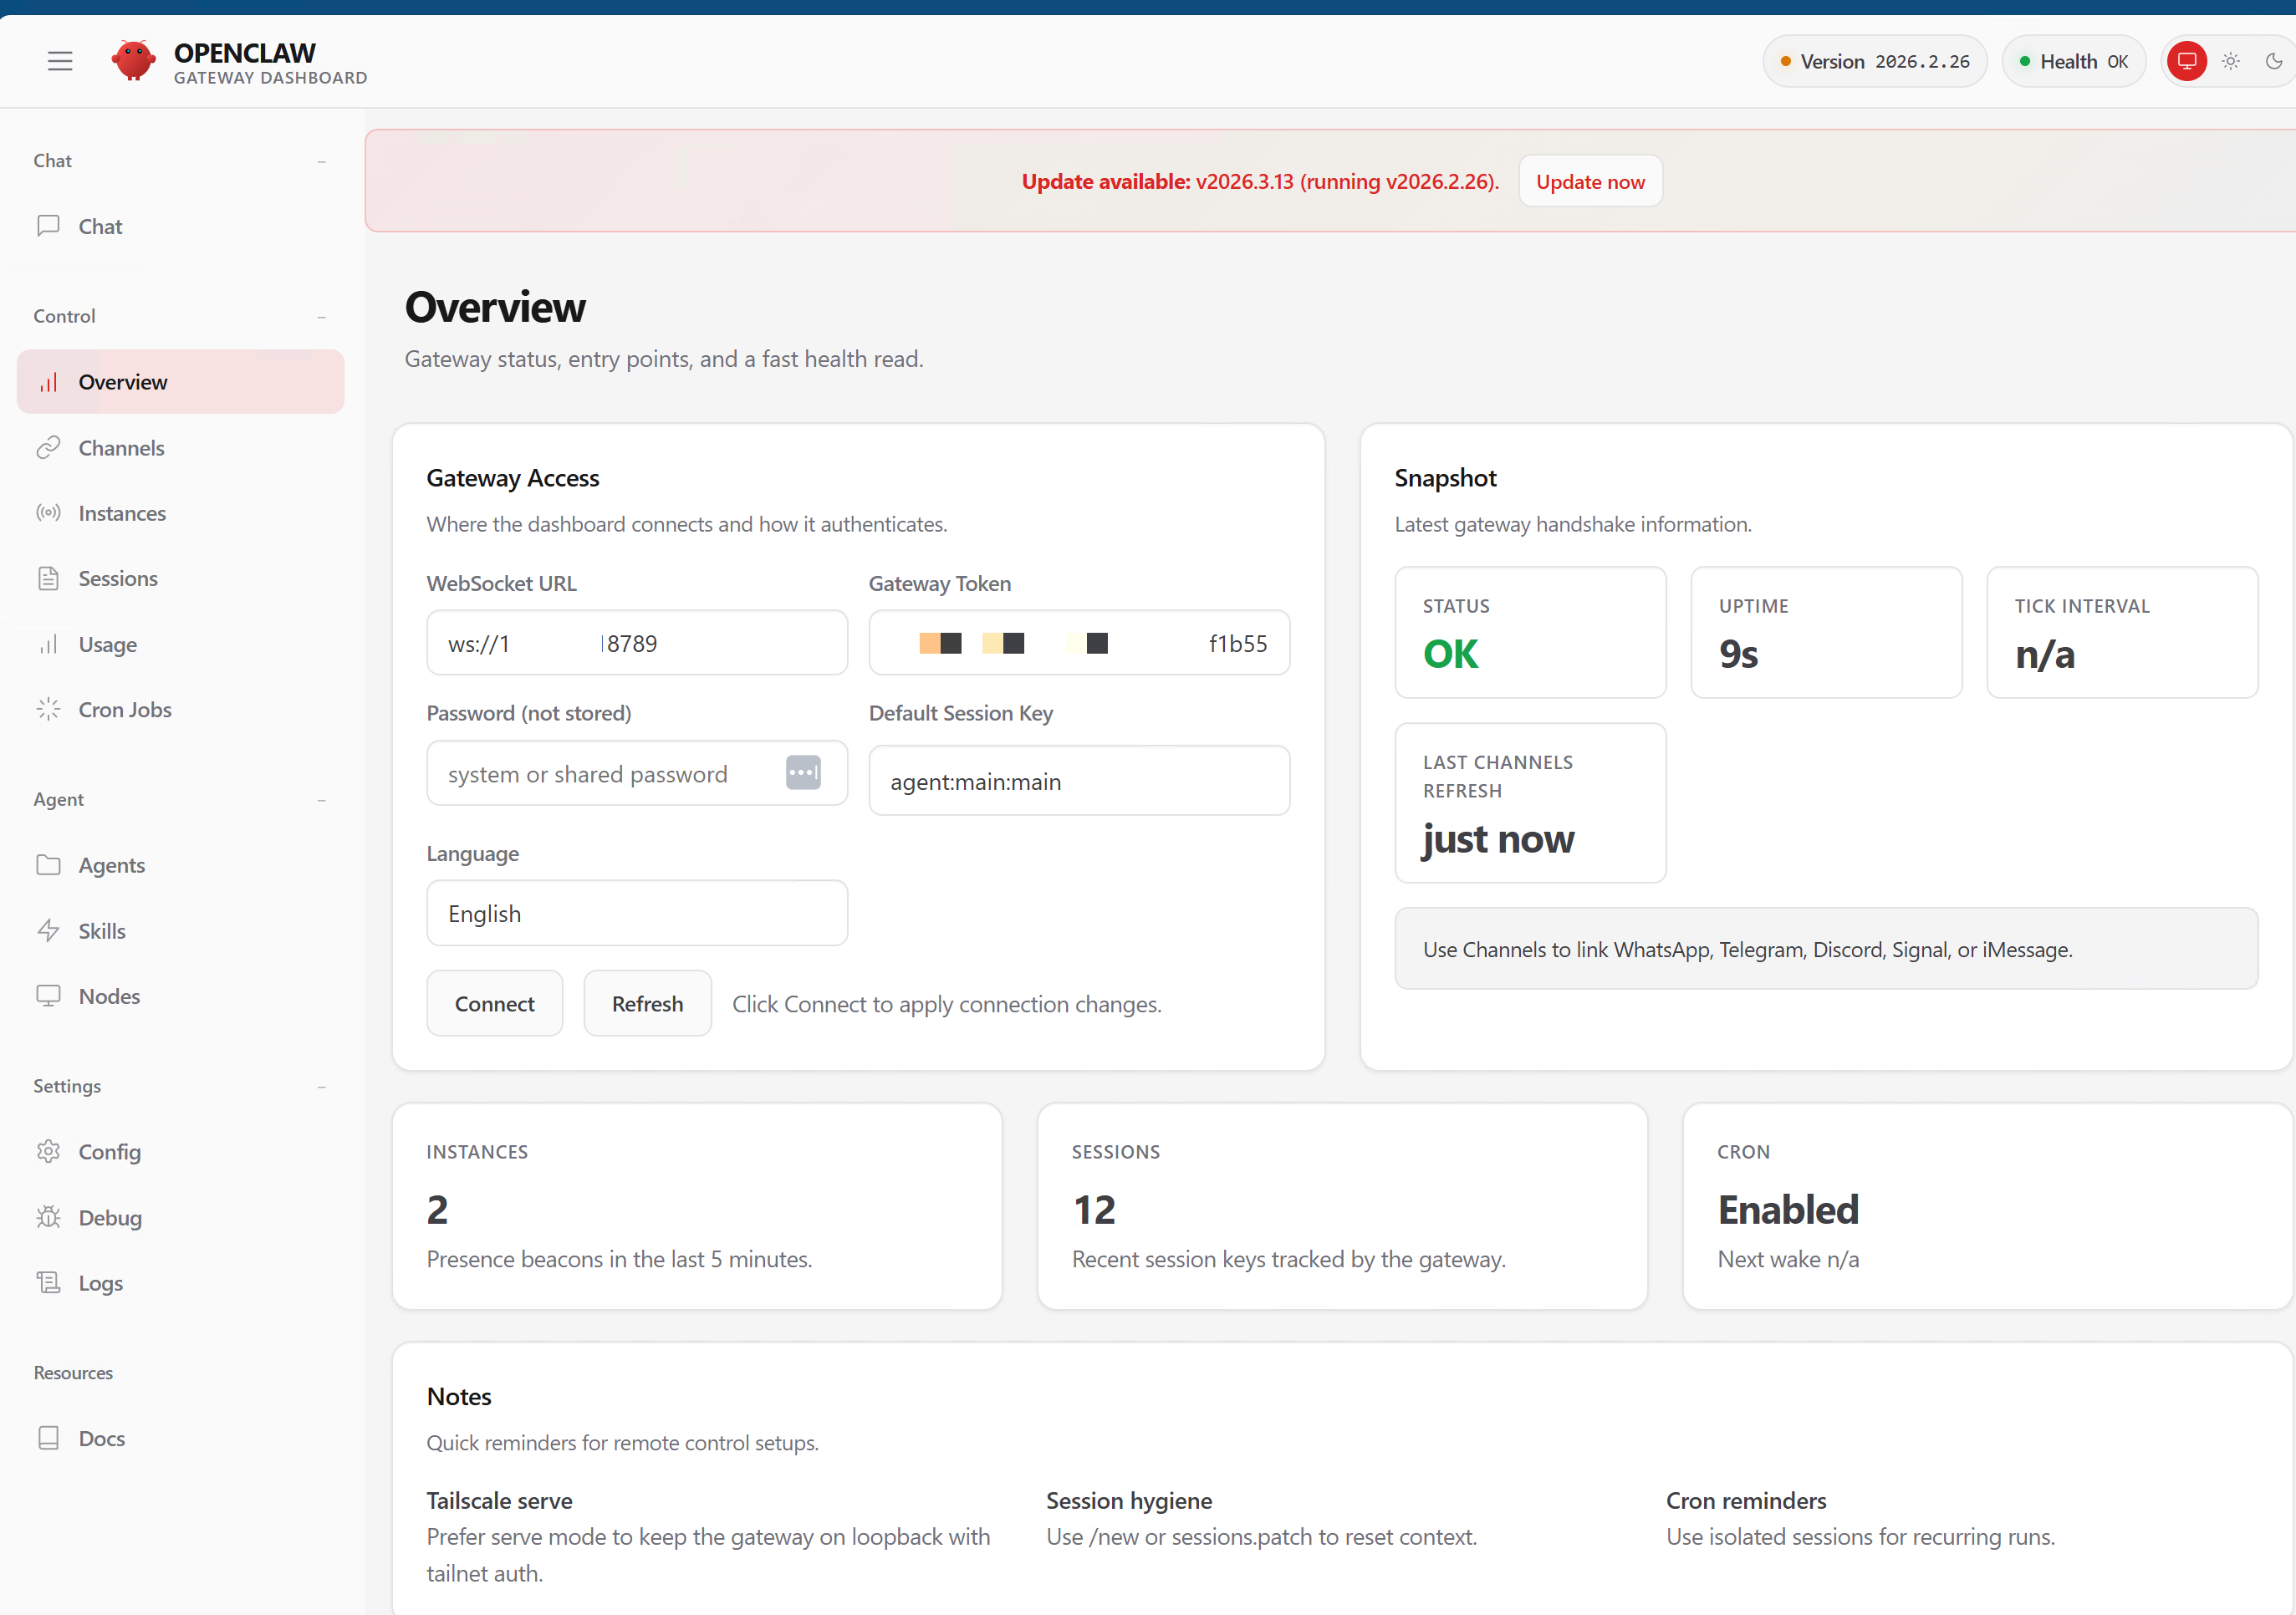
OpenClaw Gateway Dashboard showing healthy status, 12 active sessions, and cron jobs enabled

Your Next Hire Should Be an AI — Here's How a Nonprofit Did It in Two Weeks

TL;DR We deployed an autonomous AI executive assistant for a nonprofit in under two weeks. She runs eight scheduled programs daily — morning briefings, social media, donor research, newsletter drafts, content scouting, and end-of-day digests — all without being asked. The CEO went from drowning in operational work to just making decisions. The same pattern works for any small organization: medical practices, restaurants, law firms, conferences, mom-and-pop shops. “The CEO’s time should be spent on decisions, not data entry. On strategy, not scheduling. On relationships, not routine.” ...

March 17, 2026 · 6 min · Fabian Williams