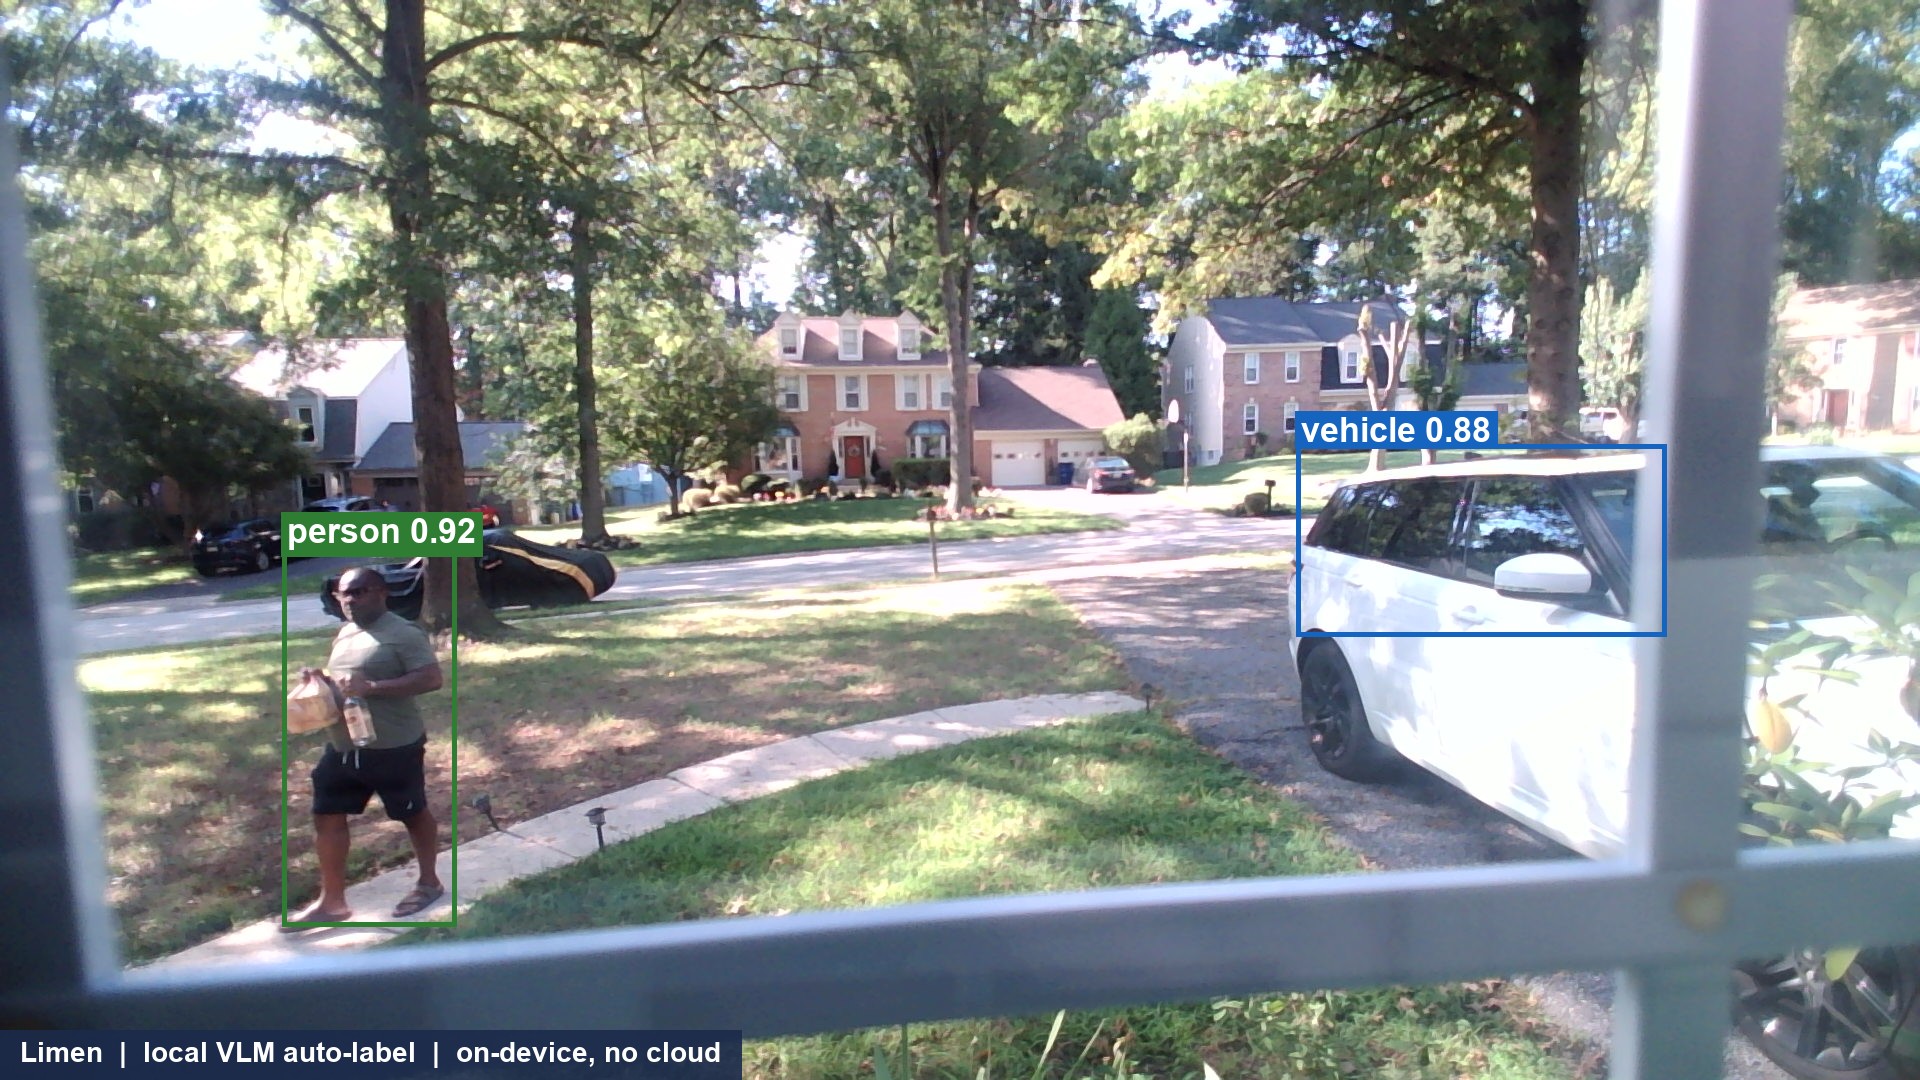
A view from a front window: a man walking up the path toward the door holding a bag and a bottle, boxed on device with a green person label, with his vehicle boxed and a blue vehicle label, and a caption reading Limen local VLM auto-label on-device no cloud

Limen: I Put a Camera at My Window and Asked Who Owns What It Sees

This week is Fix, Hack, Learn (FHL) at work (Microsoft), our internal week to chase a build we care about. Last FHL I worked on my agents and agentic loops, helping me scale myself and my work as a product manager. This time my project is personal, and it starts with a question I could not stop turning over: when a camera watches the front of my house, who owns what it sees? ...
September 14, 2026 · 9 min · Fabian Williams
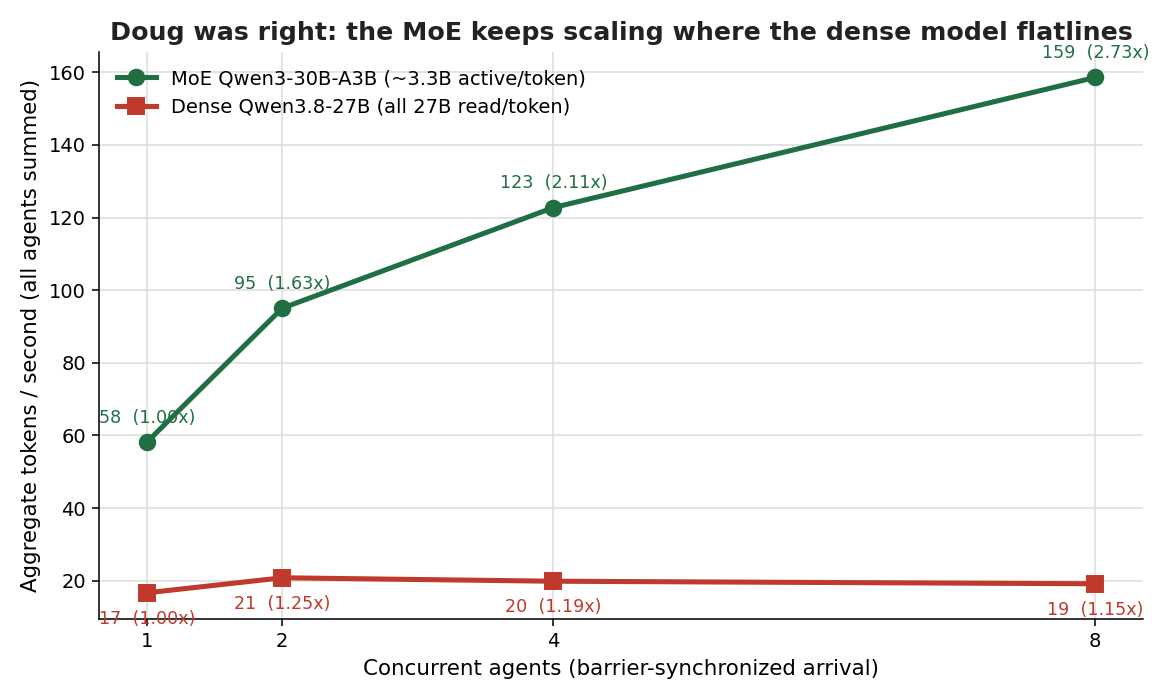
A line chart showing aggregate throughput staying flat near 20 tokens per second on a dense model while a mixture-of-experts model climbs from 58 to 159 tokens per second as concurrent agents rise from one to eight

Doug Was Right: I Swapped In The MoE, And The Concurrency Math Changed

Two days ago I posted 36 barrier-synchronized loads against 1 local model and let the numbers answer a question Reddit handed me. That post ended with a promise. A reader named Doug Ware, who builds applied AI systems for a living, had replied with the one caveat I had not tested, and I said out loud that measuring it was the next thing I would do. This is that measurement. I did not wait, I did not hand-wave it, and I kept every honest asterisk in. ...

August 20, 2026 · 9 min · Fabian Williams
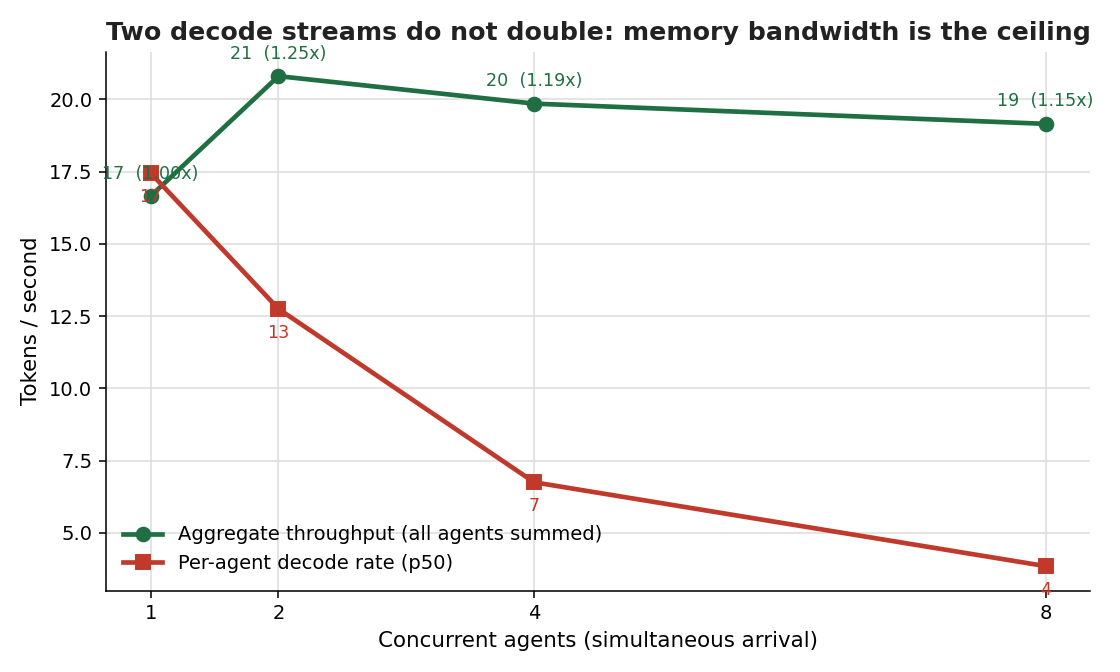
A line chart showing aggregate throughput flattening while per-agent decode rate collapses as concurrent agents rise from one to eight on one local MLX model

You Asked, So I Measured: What Concurrency Actually Costs On One Local Model

Over last week and these last 2 days in this week I posted measured answers to readers both in Twitter and Reddit who asked whether my experiments of 2 local agents on 1 Mac run in parallel or take turns. The answers was that they share one continuous batch, batching is real, and 3 quiet choices collapse it. I thought that was the end of it. It was not. The comments were better than my post, WHICH IS AWESOME, becaue this is the crowdsourcing of brain power I love. I not trying to be a KNOW IT ALL Im trying to be a LEARN IT ALL! ...

August 18, 2026 · 14 min · Fabian Williams
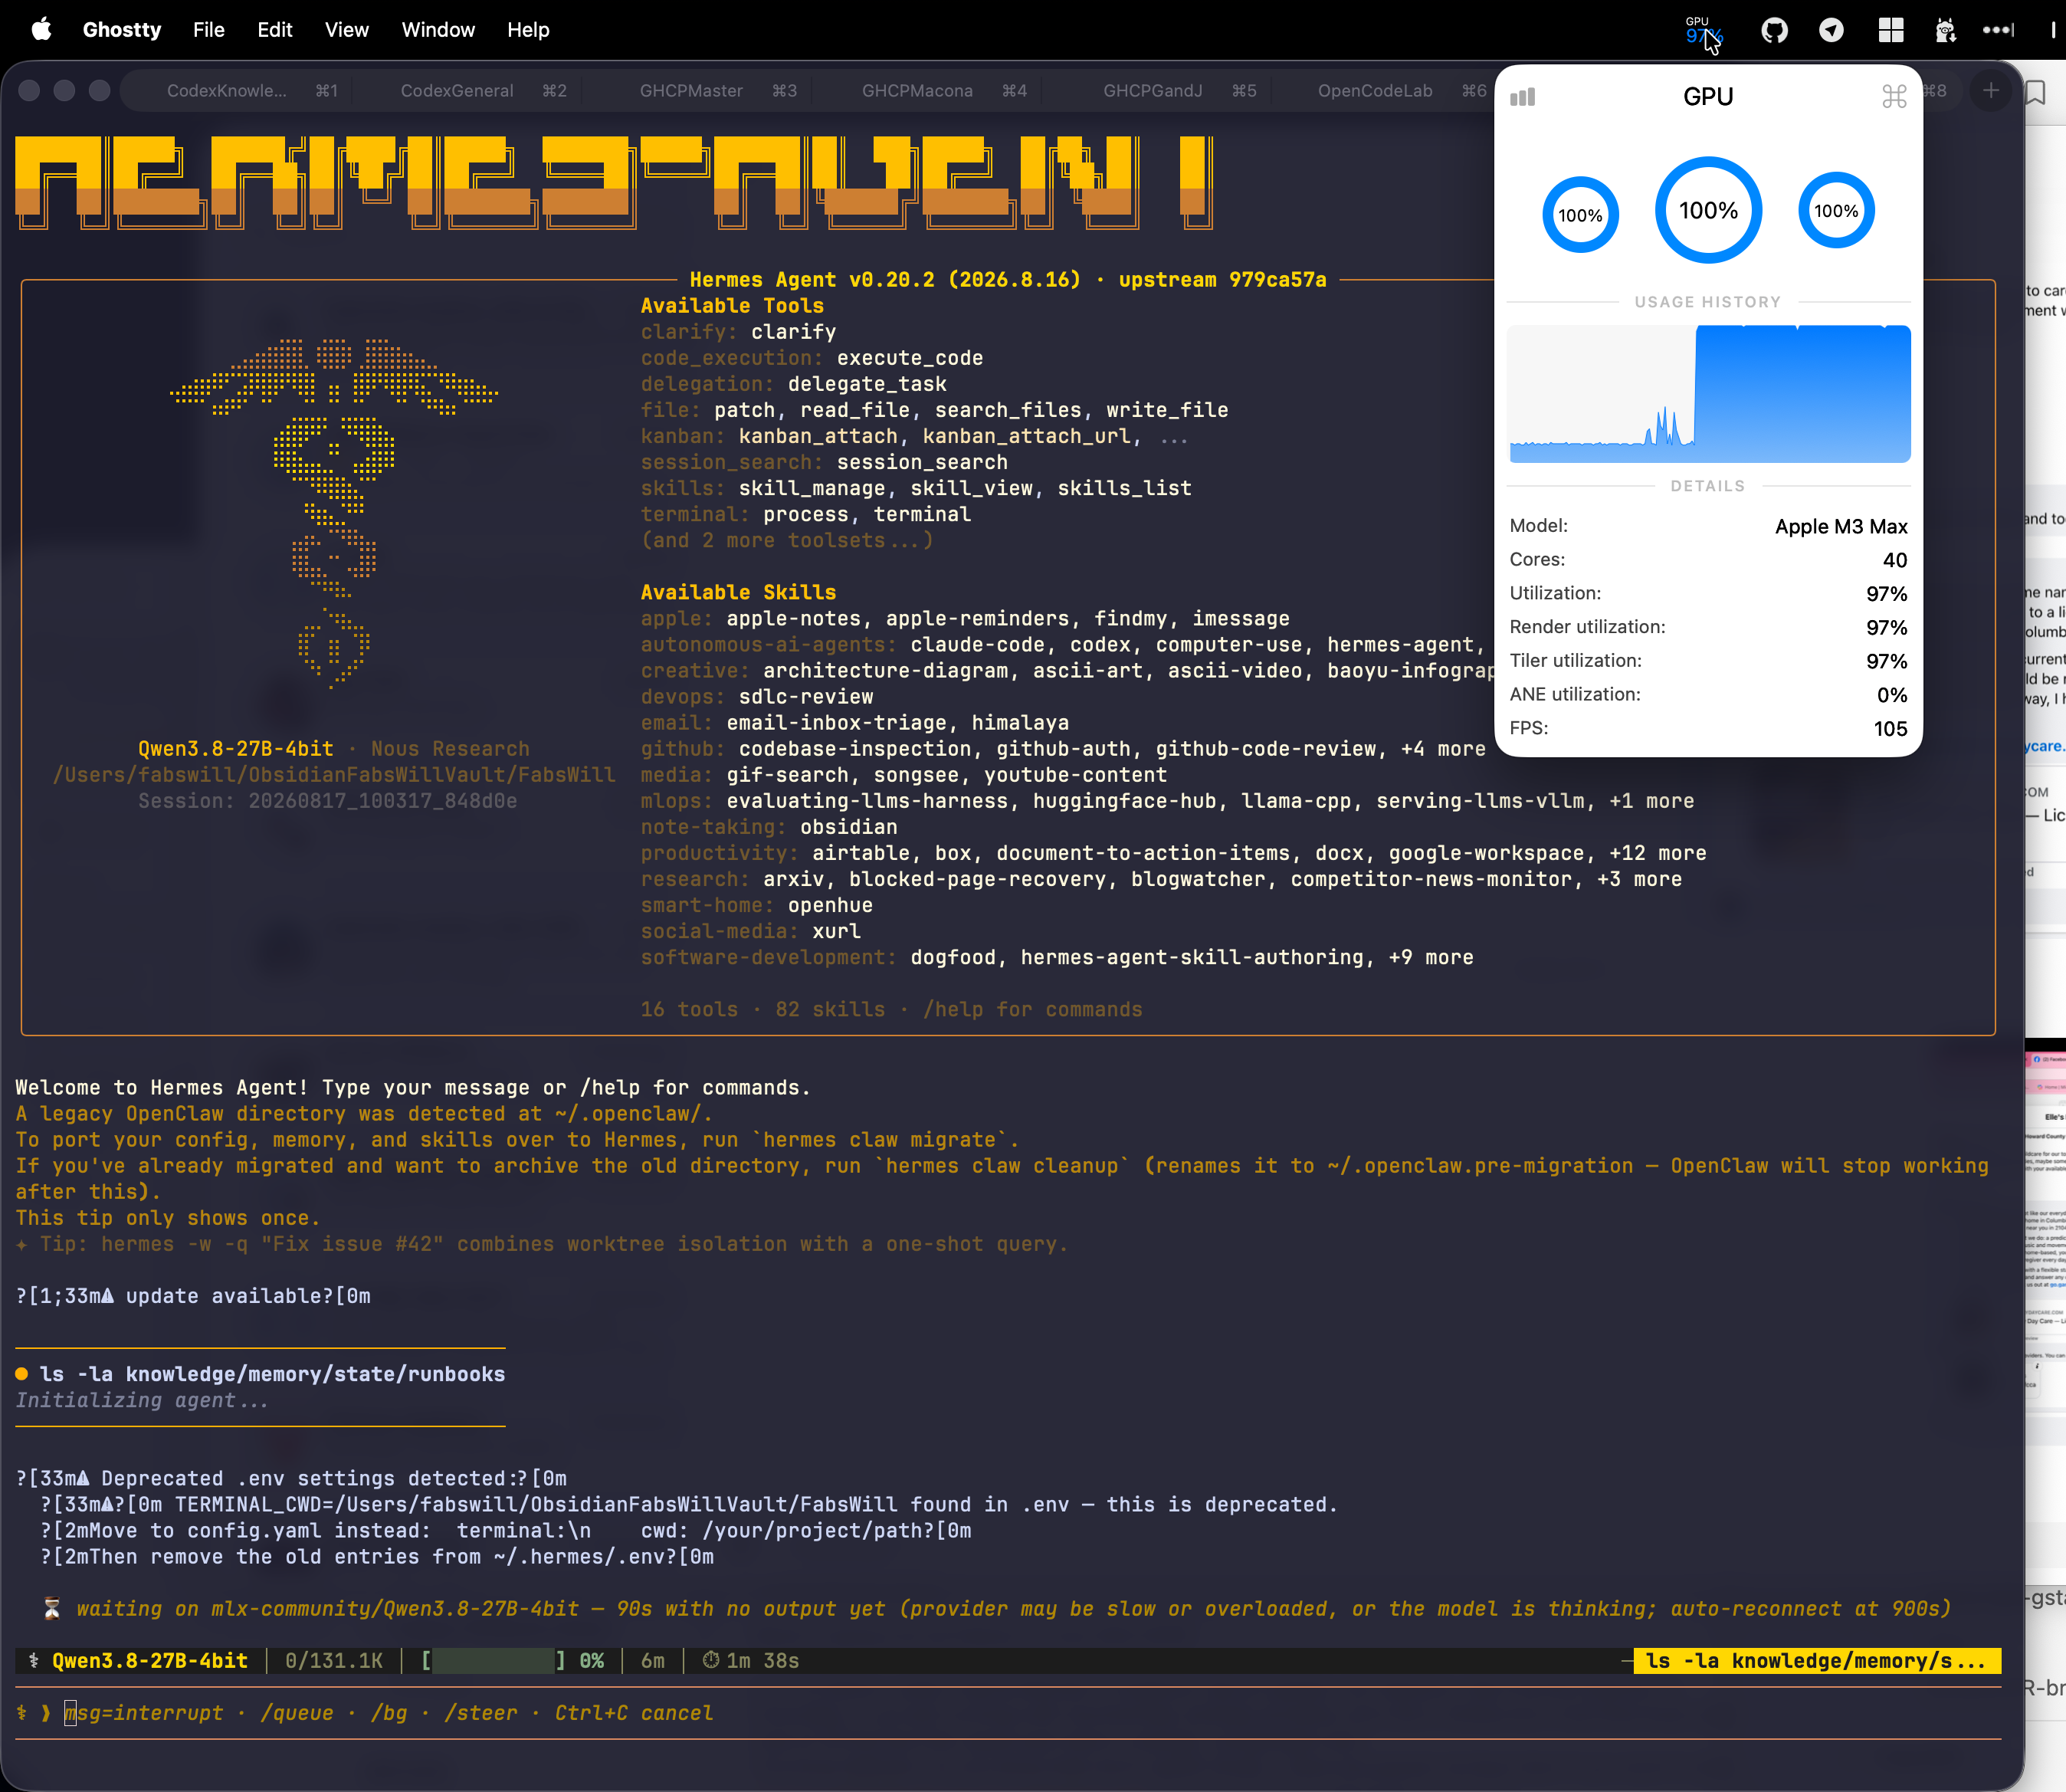
The Hermes agent running against a local Qwen3.8-27B MLX server, with the Apple M3 Max GPU pinned at 97 percent on the first turn

I Added a Second Local Agent This Week. Here Is the Receipt for Every Human Decision Behind It.

This week I trialed a second local coding agent, Hermes from Nous Research, on my own MacBook Pro M3 Max, pointed at the same local Qwen 3.8 model I already run. I installed it additively, so nothing already working could break, governed it with manual approvals, and did not stop until it proved it behaves. Here is the trial, in tables and screenshots. One housekeeping note before the story. Last week’s post got called AI slop on Reddit. My full answer to that, and the standing standard I now hold my writing to, lives on its own page: On Slop, And Who Gets To Call It That. It is not the point of this post, so I moved it out of the way. Back to Hermes. ...

August 17, 2026 · 7 min · Fabian Williams
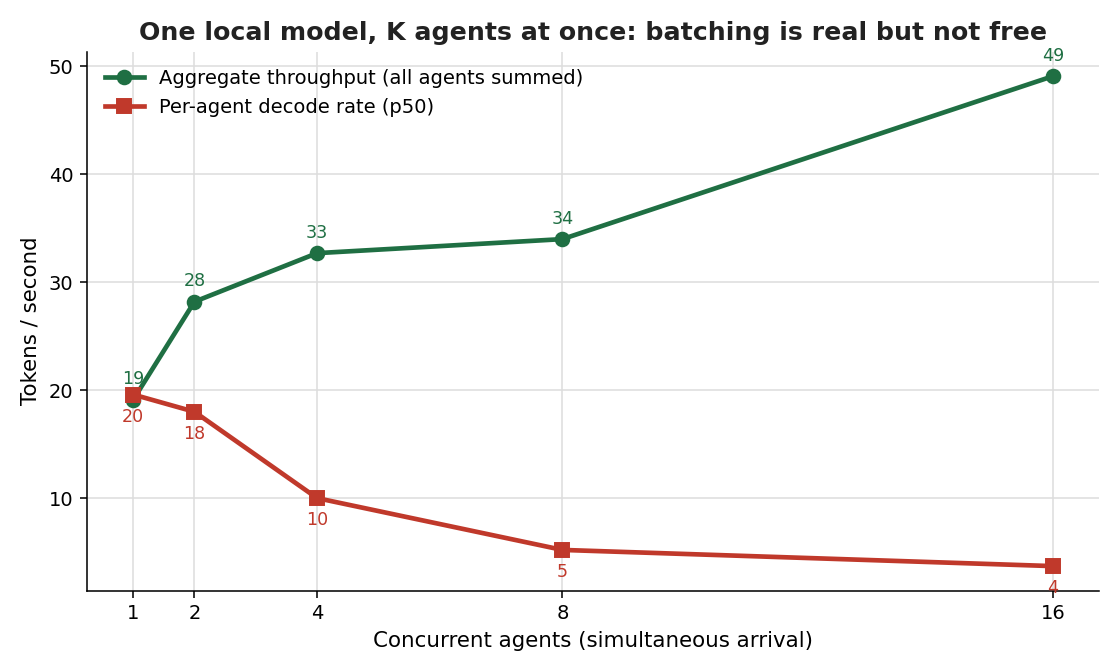
A line chart showing aggregate throughput rising with concurrent agents while per-agent decode rate falls, on one local MLX model

Two Agents, One Local Model: Do They Run in Parallel, or Take Turns? I Measured It.

A reader on Reddit asked me a sharp question about my last post. I had trialed a second local coding agent, Hermes, pointed at the same local Qwen 3.8 model my other agent already uses. His question was simple. Did I ever run both agents at the same time, two separate harnesses hammering one model on one Mac at once. And what about Hermes spawning its own sub-agents against that same endpoint. Is any of that predictable. ...

August 17, 2026 · 9 min · Fabian Williams
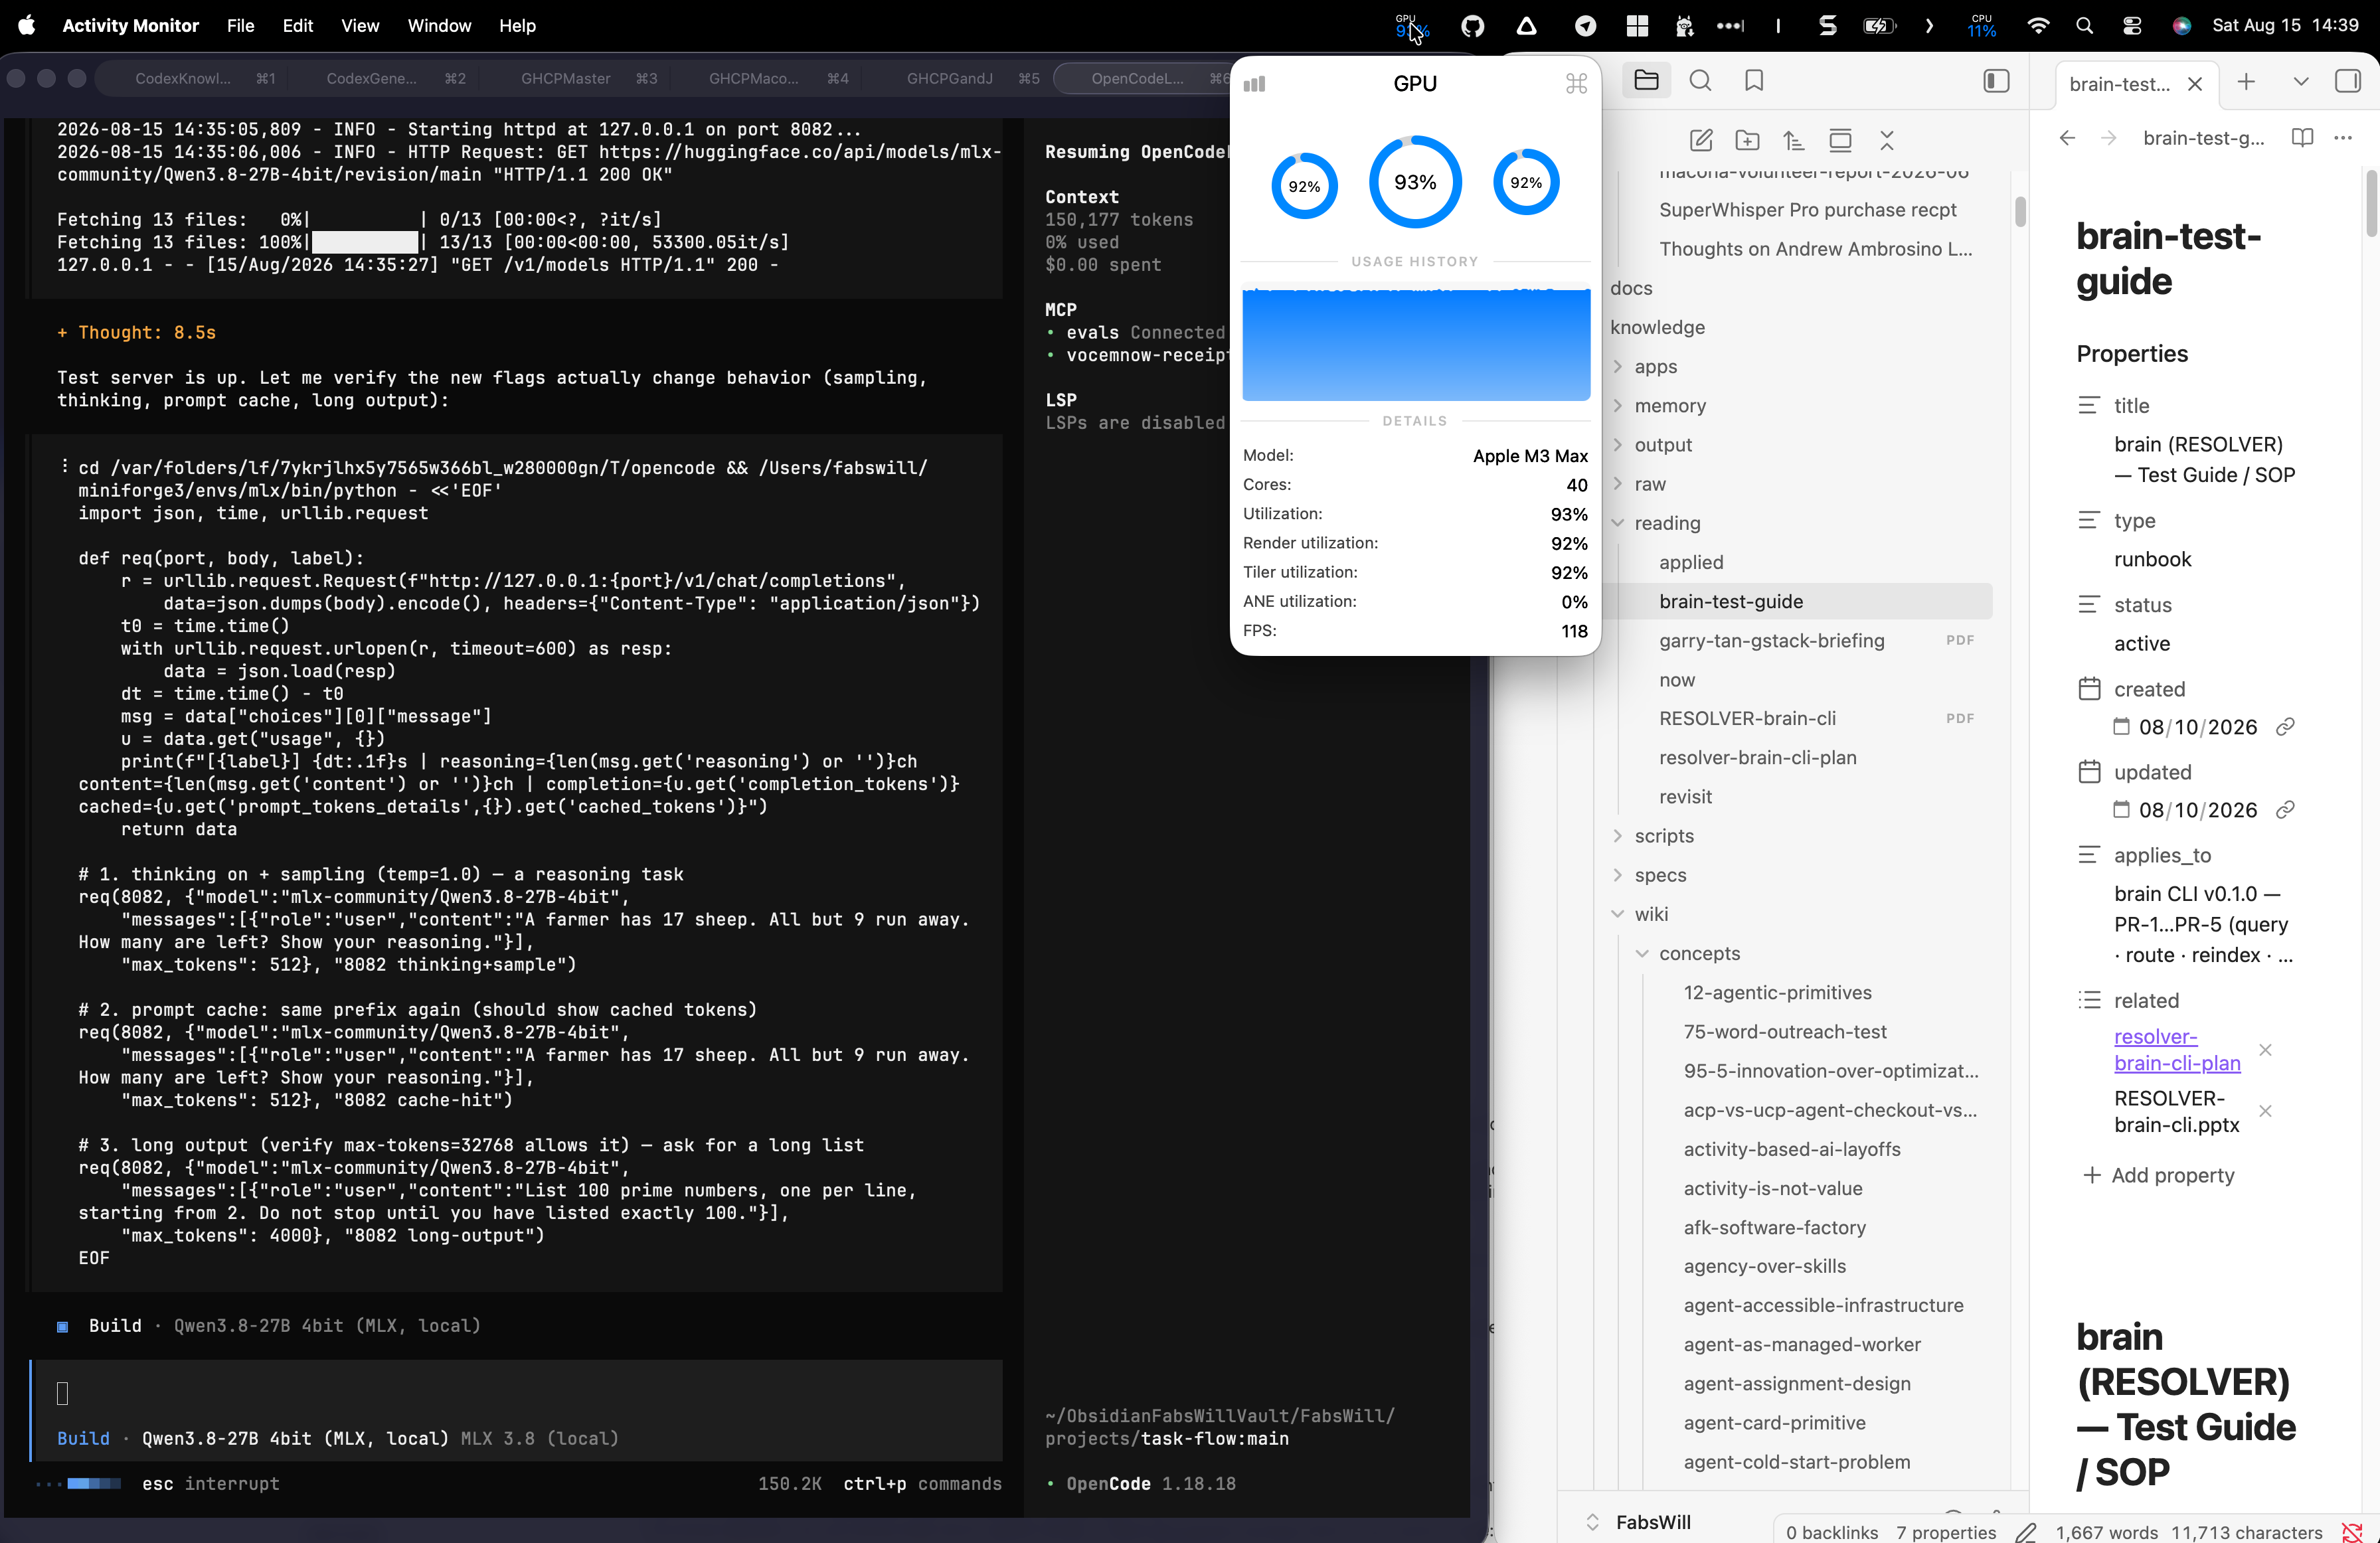
Activity Monitor showing the M3 Max GPU pinned at 92 percent while an OpenCode agent runs probe requests against a throwaway Qwen3.8 test server on port 8082

I Swapped My Local Coding Model Overnight From a Hotel. The Agent Graded the Upgrade Itself.

TL;DR Local models are how I run my community work, my volunteer projects, my side hustles, and my musings. Two reasons, both simple: Cost. None of this work should bill against a frontier account. Trust. Client and customer data stays on my own disk, away from the labs. Bottom line up front: I am running Qwen3.8-27B (4-bit) on my MacBook Pro M3 Max, 128 GB of unified memory and a 40-core GPU, my personal dev rig, driven by an OpenCode harness. ...

August 15, 2026 · 8 min · Fabian Williams
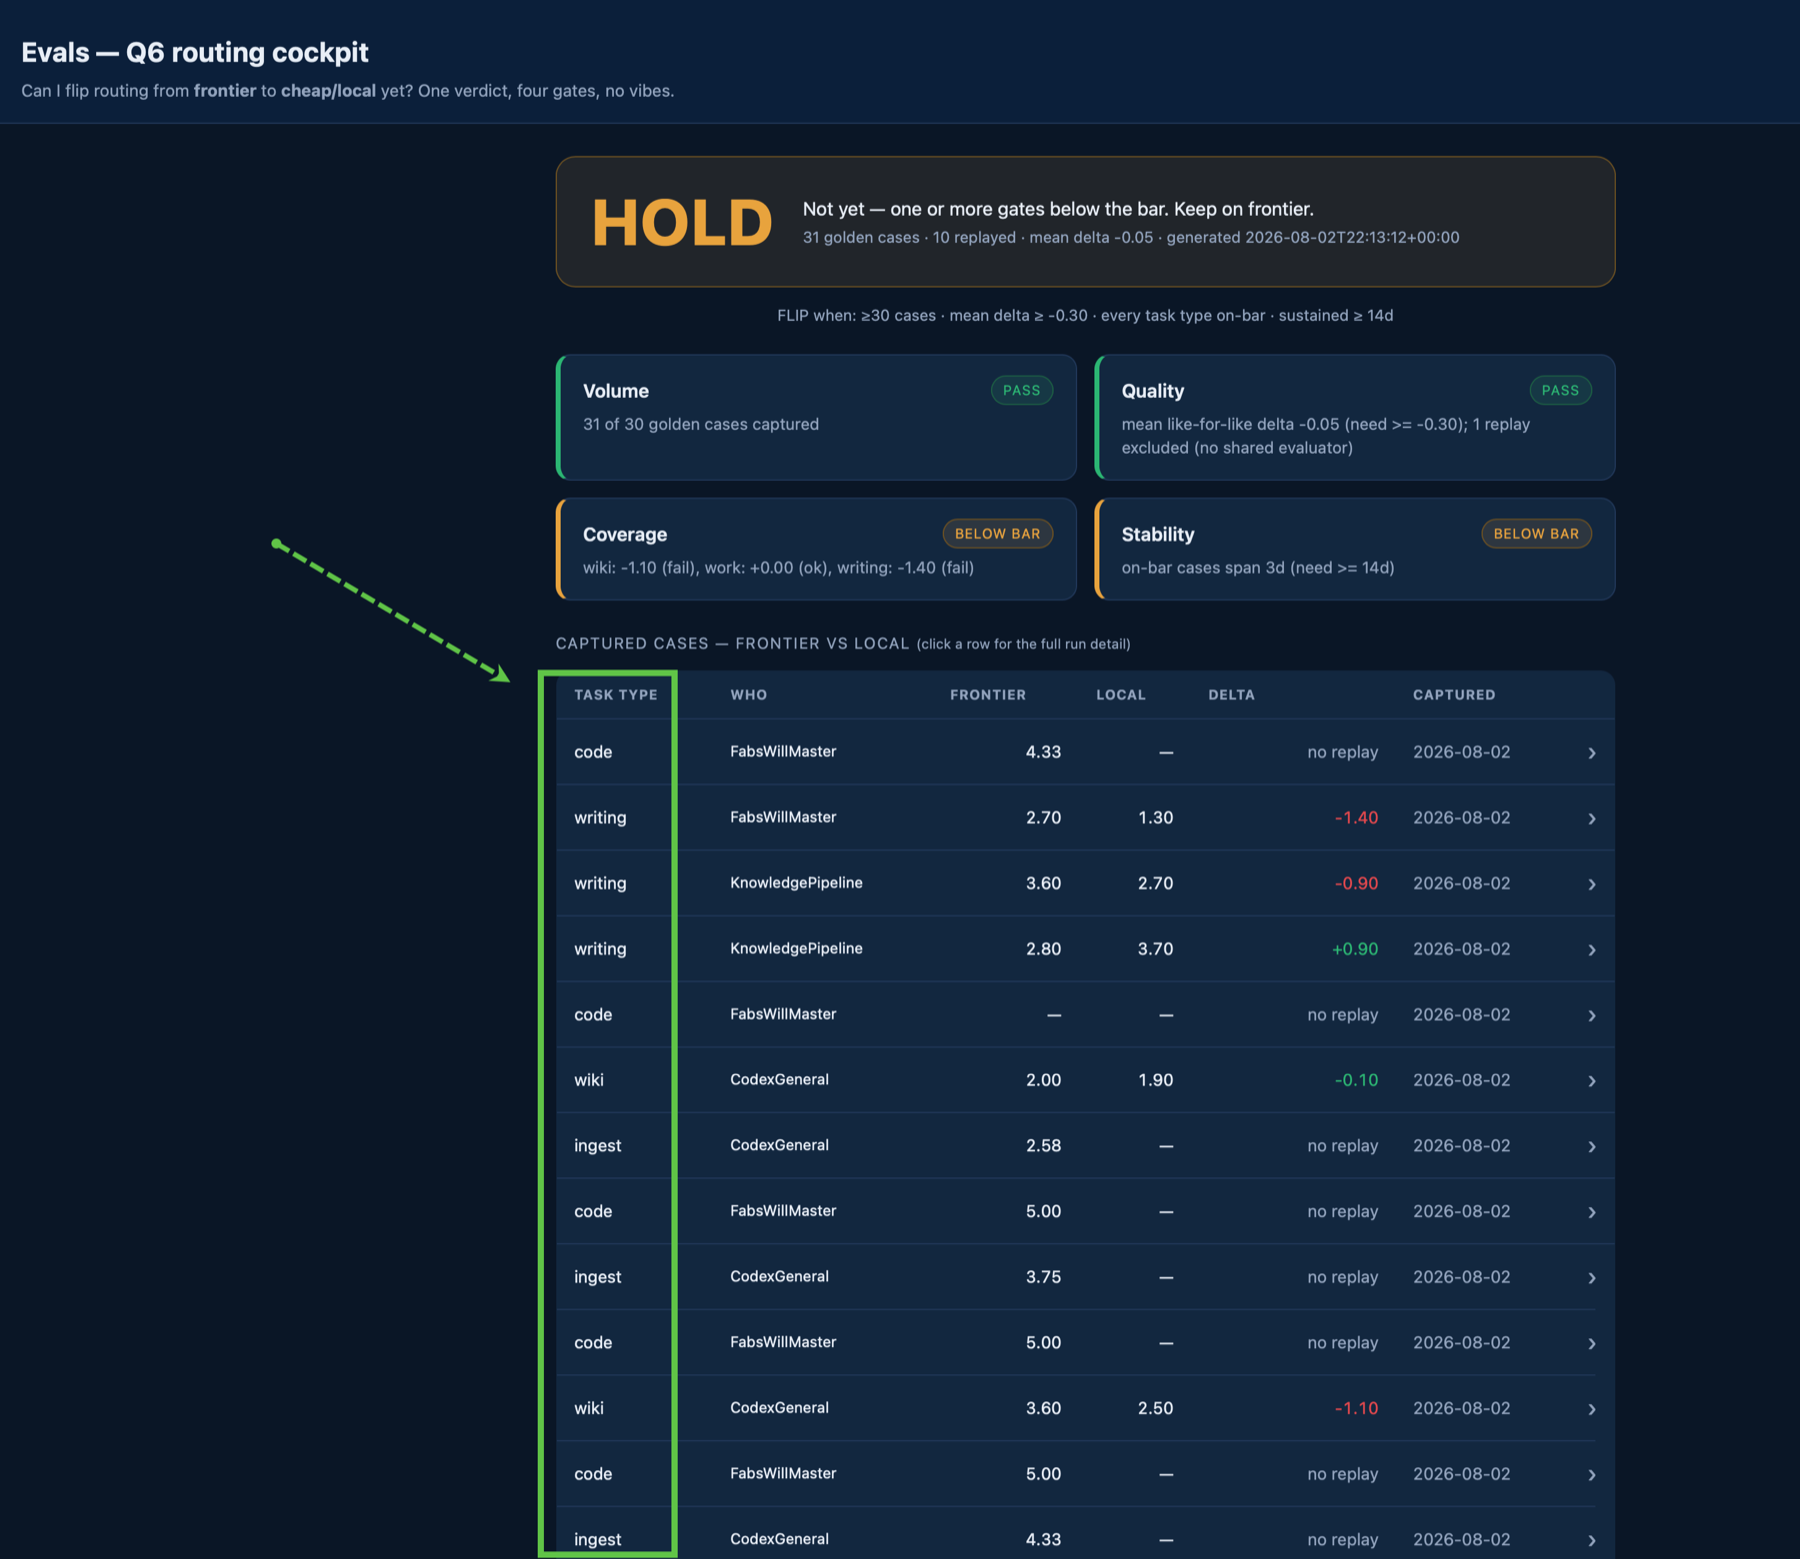
Eval cockpit showing the verdict panel: 31 golden cases, 10 replayed, mean like-for-like delta -0.05, with Volume and Quality gates passing

I Made My Evals Replay Every Task on a Local Model. The Frontier Lead Got Thin.

TL;DR My agents do real work on frontier models. Every dollar of that work is metered against my OpenAI and Anthropic bills. Meanwhile a perfectly capable local model, gpt-oss:20b, sits on a Mac Mini in my office costing me nothing. The obvious question: for which tasks could the free local model do the job just as well? Today I answered it with a system instead of a guess. I taught my eval framework to automatically replay every writing task on the local model right after the frontier model runs it, then grade both with the same judge and record the gap. The result across 10 like-for-like rematches: a mean quality delta of -0.05 — statistical parity — and four tasks where the local model actually scored higher than the frontier model, by as much as 1.7 points. ...

August 2, 2026 · 7 min · Fabian Williams
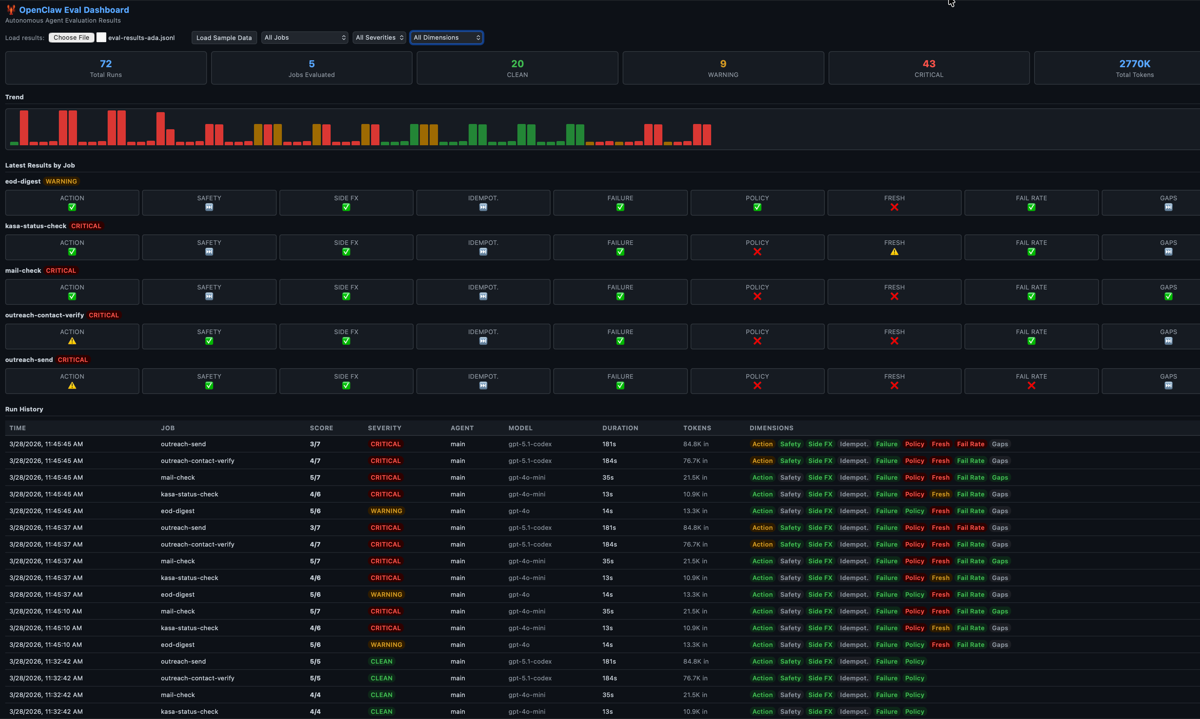
OpenClaw Eval Dashboard showing mixed results across 9 dimensions — the honest picture after adding freshness, failure rate, and delivery gap scoring

How Do You Trust an Autonomous AI Agent? Evals Are the Answer.

TL;DR I run an autonomous AI agent on a Mac Mini in my house. She handles 16 daily cron jobs — finances, email triage, outreach campaigns, device monitoring, morning briefings. The agent says “done.” But did it actually do anything? I built a 9-dimension eval rubric to find out. Along the way I discovered that my evals were broken, my agent was better than I thought, and the most important metric isn’t pass/fail — it’s whether a failure is your fault or the agent’s fault. ...

March 28, 2026 · 10 min · Fabian Williams
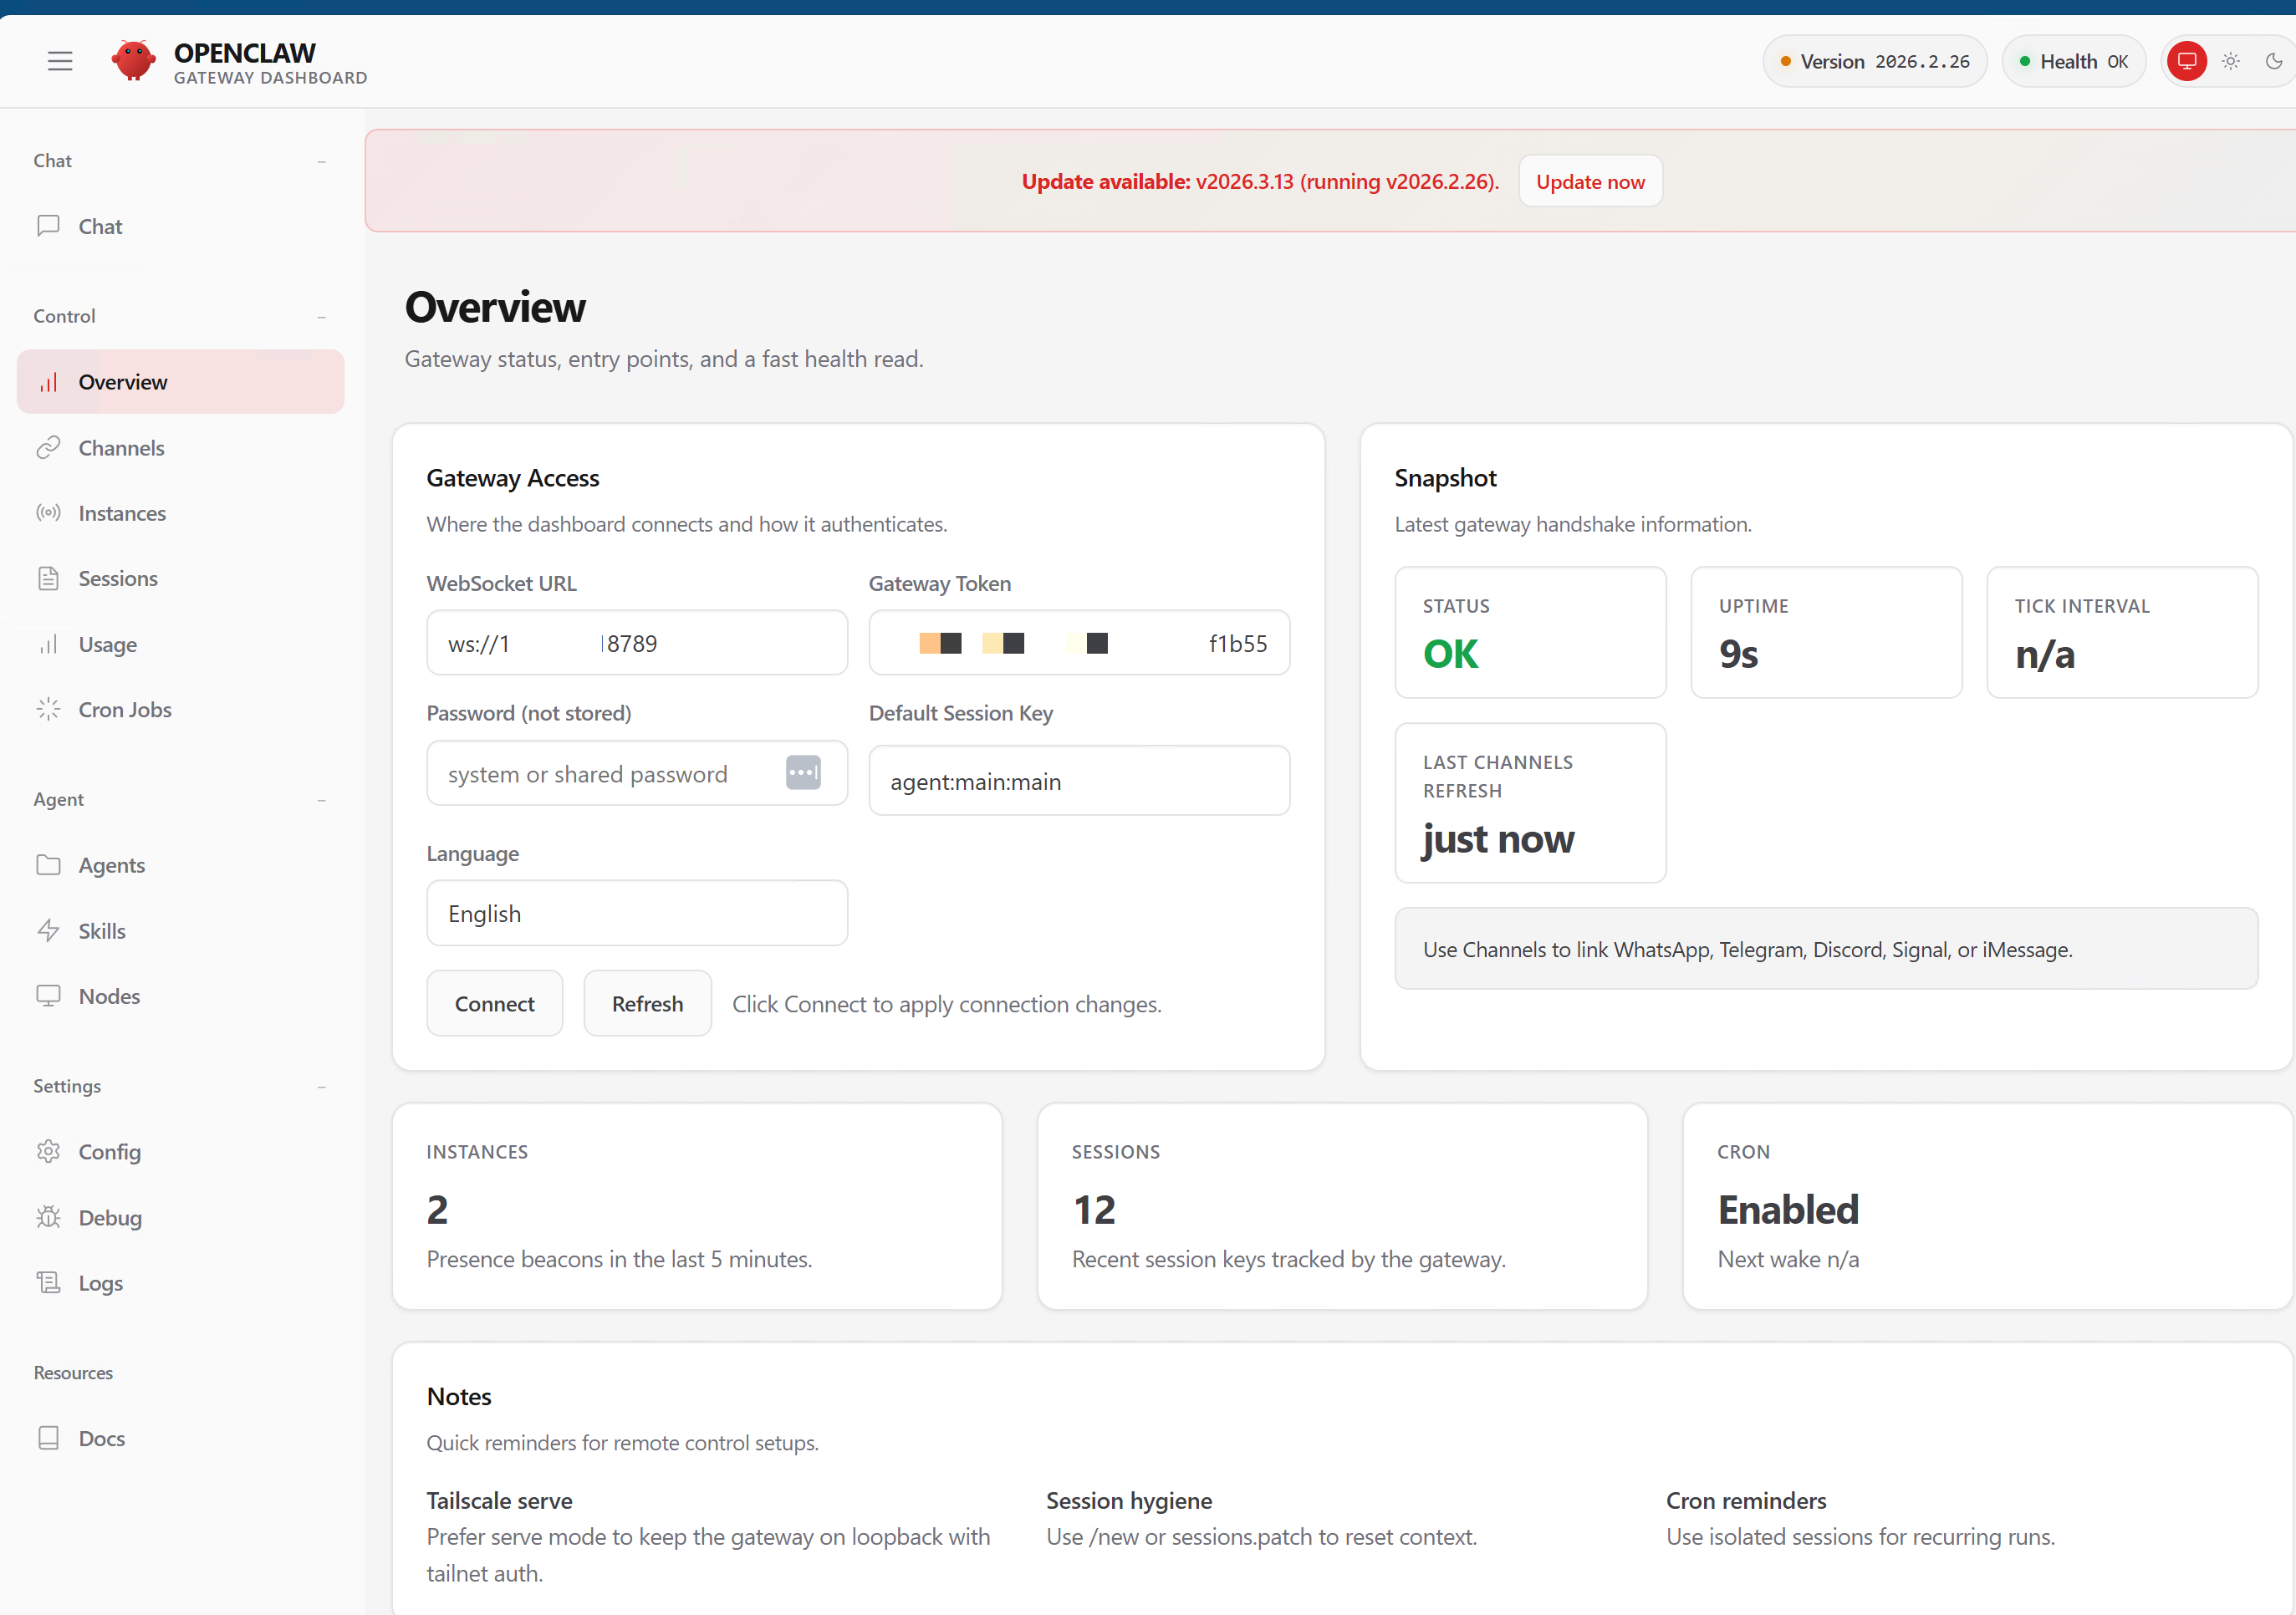
OpenClaw Gateway Dashboard showing healthy status, 12 active sessions, and cron jobs enabled

Your Next Hire Should Be an AI — Here's How a Nonprofit Did It in Two Weeks

TL;DR We deployed an autonomous AI executive assistant for a nonprofit in under two weeks. She runs eight scheduled programs daily — morning briefings, social media, donor research, newsletter drafts, content scouting, and end-of-day digests — all without being asked. The CEO went from drowning in operational work to just making decisions. The same pattern works for any small organization: medical practices, restaurants, law firms, conferences, mom-and-pop shops. “The CEO’s time should be spent on decisions, not data entry. On strategy, not scheduling. On relationships, not routine.” ...

March 17, 2026 · 6 min · Fabian Williams